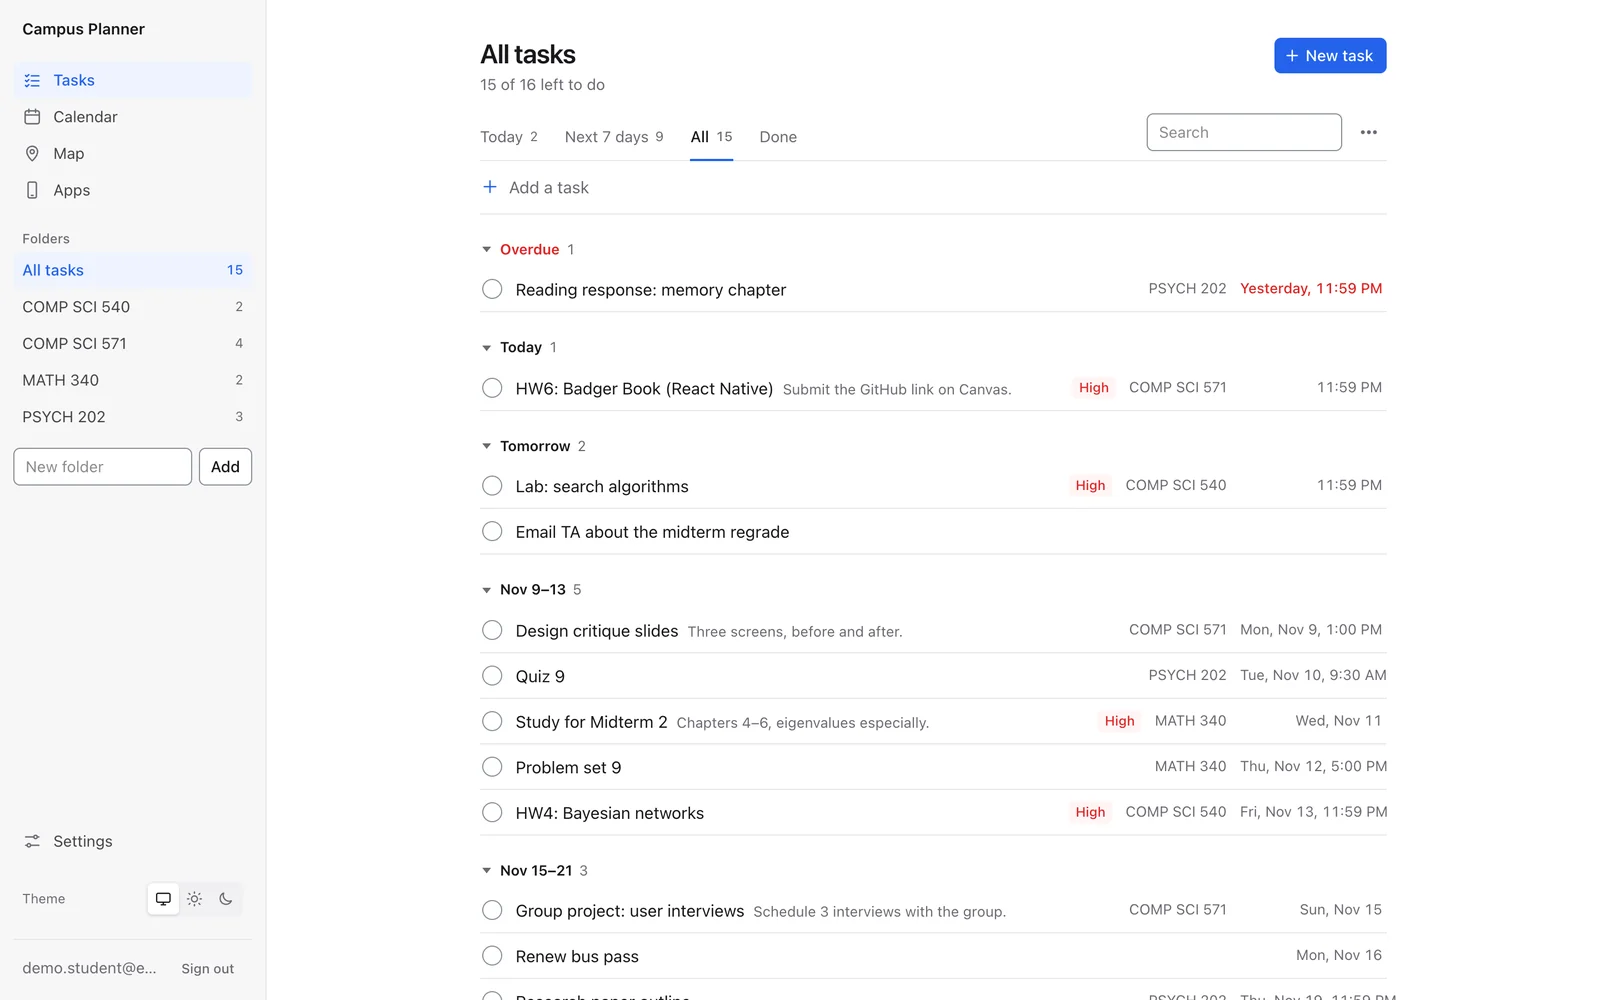
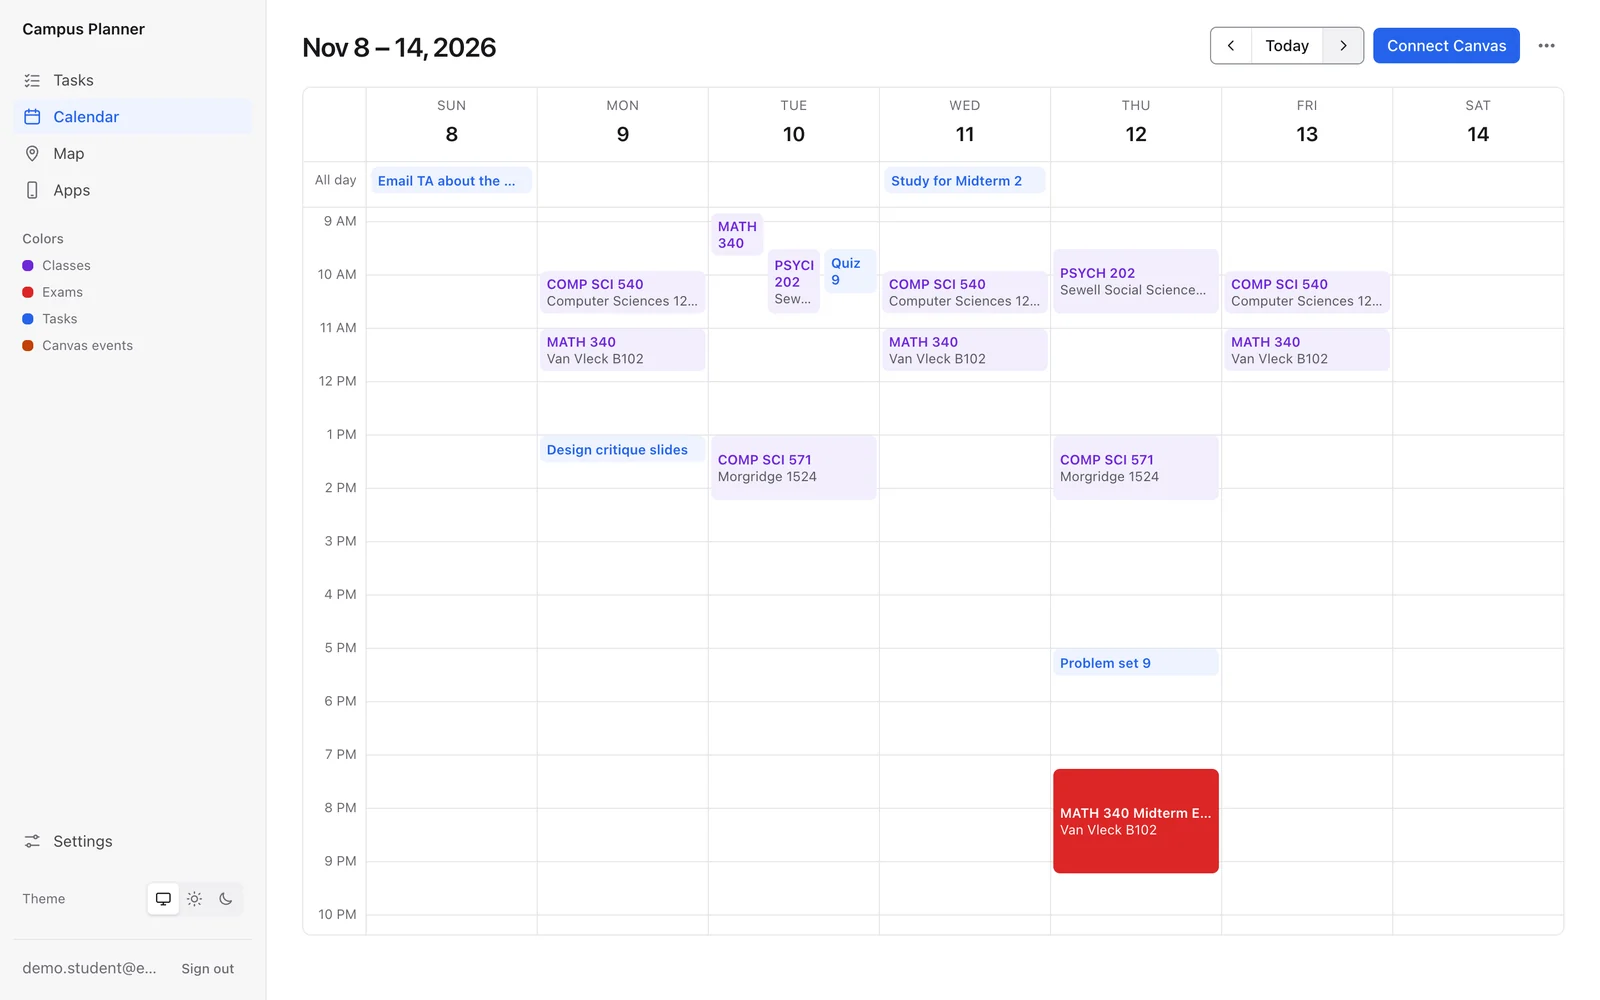
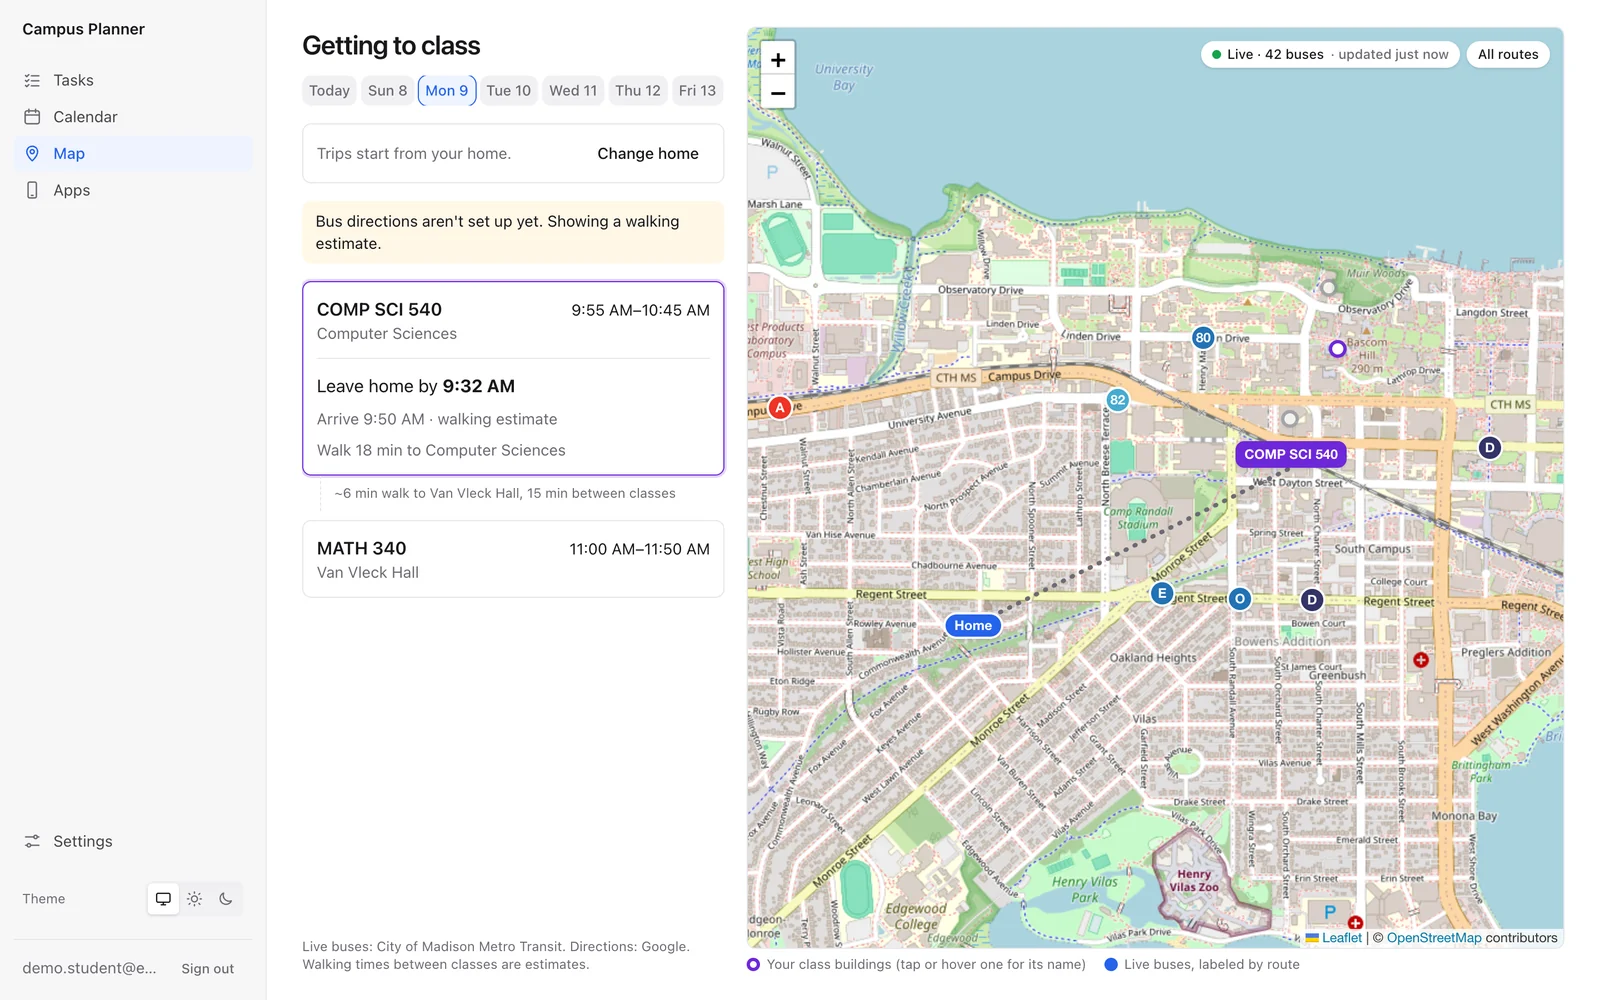
One place for school at UW–Madison: tasks in folders, a week calendar of classes, exams and Canvas assignments, and a campus map that says when to leave for class, with live Madison Metro buses.
It started as my CS 571 (Building User Interfaces) project. I built it on my own: a website, an Android app, a Chrome extension, and a connector that lets AI assistants read the planner.
Imports a class schedule pasted from UW’s Course Schedule page, read by Claude Haiku.
Syncs Canvas files, announcements and assignments to your computer or Google Drive; assignments become tasks and get checked off when submitted.
Lets Claude, ChatGPT, Claude Code and Codex read your schedule and course files over MCP, read-only.
Combining battery-service records with Census data to understand pricing patterns and explore potential expansion markets.
I used weighted and geographically weighted regression, spatial autocorrelation tests, and held-out markets to evaluate how well demand models transfer to new places.
Maintained customer records in Excel and analyzed underserved segments and potential customer bases for marketing campaigns.
DIFY Battery · Austin2021–23 +
Lead Technician · Self-employed
Launched the Austin market and grew monthly sales from $0 to $40K+, managing service requests, installations, scheduling, and inventory. Trained the incoming technician.
What I’m learning
University of Wisconsin–Madison
B.S. Data Science · Computer Science certificate
Relevant coursework9 courses +
A closer look at the topics and coursework.
Data Science Modeling ISTAT 240 +
R & RStudio, vectors and data frames
Exploratory analysis, descriptive statistics and visualization
Data cleaning and transformation with dplyr
Probability, sampling and inference for means, proportions and regression
K-nearest neighbors, Naive Bayes, decision trees and linear models
Neural networks, support vector machines and optimization
Clustering, dimensionality reduction and self-supervised learning
Model evaluation, ensembles, link analysis and language modeling
Course project: team proposal, presentation, final report and code
Advanced Quantitative AnalysisGEOG 560 +
Statistical and spatial analysis in R
Multiple regression, spatial autoregression and geographically weighted regression
Bayesian inference, categorical prediction, SVMs and decision trees
Multivariate methods, principal components and time series
Coursework: five labs covering regression, spatial data, categorical prediction, SVMs/trees and multivariate methods; an independent data-analysis project
Artificial IntelligenceCS 540 +
Probability, linear algebra, PCA and natural language processing
Clustering, classification and regression
Neural networks, deep learning and generative models
Search, games, reinforcement learning and AI ethics
Built: PCA face compression, an n-gram text generator, hierarchical clustering of countries, gradient-descent regression, A* search, PyTorch image classifiers (Fashion-MNIST, CIFAR-100) and a fine-tuned DistilGPT-2
Binary search trees, rotations, red-black trees, AVL trees and B-trees
Graphs, minimum spanning trees and shortest paths
Sorting, hash tables, tries and skip lists
Bash, JUnit, Git, SSH, Make, code review and integration
Lambda expressions, HTML/CSS, JavaScript, web servers, JavaFX and regular expressions
Course projects: binary search tree and rotation implementations, red-black tree, iterator, shortest path and hash table; role-based development and two integration milestones
Programming IICS 300 +
Object-oriented design, interfaces, generics and exception handling
Lists, stacks, queues, heaps and binary search trees
Recursion, searching, sorting and complexity analysis
Iterators, file I/O and testing boundary conditions
Coursework: multi-class programming assignments using array-based and linked data structures
A visual walkthrough of things I’ve built and analyzed. No code, just what I did and what I found. Swipe or use the arrows to flip through each one.
Software
Campus Planner
CS 571 · Next.js, Expo, Supabase
One place for school at UW–Madison. I built it solo: a Next.js website, an Android app, a Chrome extension that syncs Canvas, and an MCP server so AI assistants can answer “what’s due?” from your real schedule.
1Tasks sit in folders, one per class, and group themselves by due date. This is the app running locally with its built-in example data.
paste the UW Course Schedule pageClaude Haiku reads the classesCanvas calendar feed adds assignmentstasks, calendar and map in one place
2Set up once from things students already have, not manual entry. Classes stop at the start of finals, and each class can get its own task folder.3The week view puts classes, exams and tasks together, so a midterm on Thursday night shows up next to everything else due that week.
Chrome extension or the Android appreads Canvas with your own sign-infiles to your computer or Google Driveassignments become tasks, submitted ones get checked off
4Canvas tokens are turned off at UW, so the sync runs inside your own Canvas session and the server never sees the sign-in. The phone app re-syncs every night on Wi-Fi, uploading only what’s new.
Settings → Connect an AI assistanta secret, read-only MCP linkClaude, ChatGPT, Claude Code, Codexget_schedule · get_tasks · find_course_files
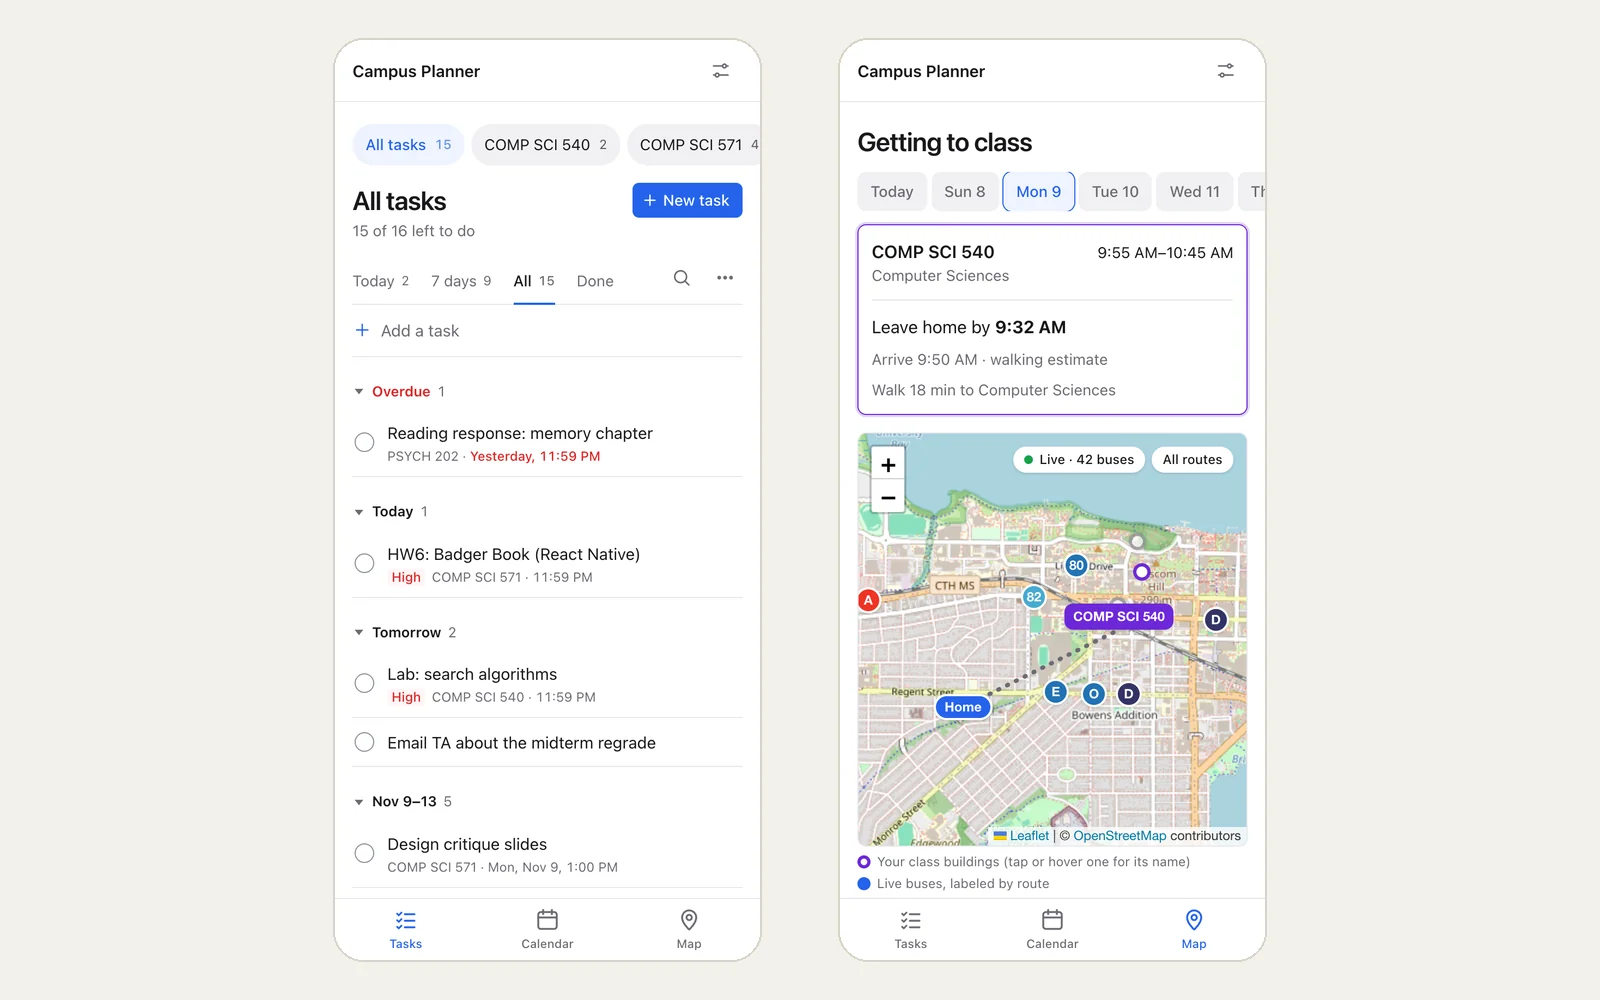
5The same link works in every AI app, and making a new one turns the old one off everywhere. A local server adds the downloaded course files, PDFs included.6The map answers when to leave for class, with live Madison Metro buses on top. Here it falls back to a walking estimate; with Google Routes set up it plans the bus. Paid lookups sit behind a cache and a daily cap so the whole app runs on free tiers.7On a phone the site switches to a bottom tab bar. The Android app (Expo) uses the same account and data.
1 / 7
what I found: a planner only works if students never keep a second list, so every import has to land in the right place on its own.
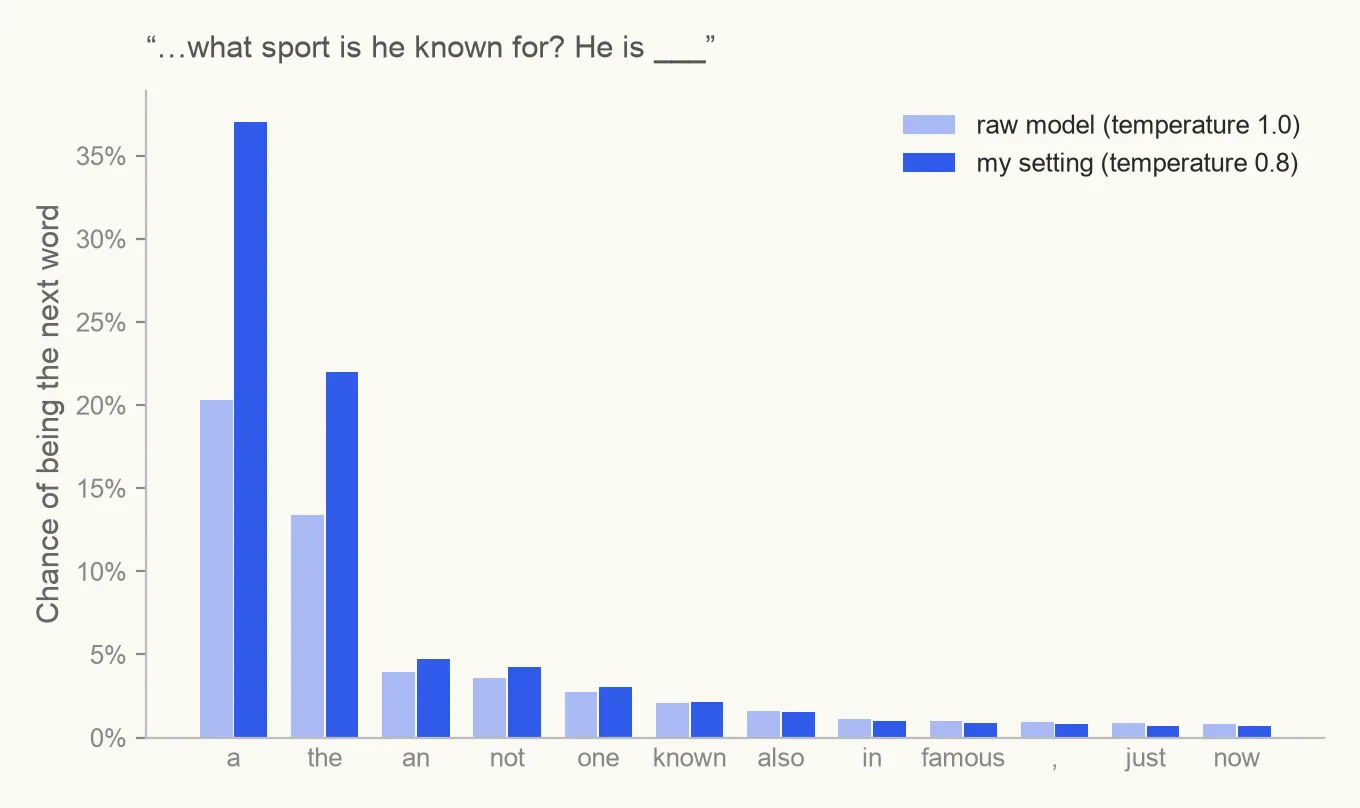
I took DistilGPT-2, a pretrained language model, trained it further on a small text dataset entirely on a laptop CPU, then studied how the sampling settings shape what it writes.
LLM fine-tuningHugging Face Transformerstokenizationtext generation
~3,000 lines of textsplit 95% train · 5% held outtokenized to 128-token chunks600 training steps on CPUfine-tuned model saved
1The pipeline. I tuned the run to finish in about 15 minutes with no GPU, using small batches, gradient accumulation and a low learning rate.2The model scores all 50,257 possible next tokens. A temperature of 0.8 sharpens its favorites, and top-p of 0.95 then drops the long tail, so only about 200 tokens stay in play here.
Prompt: What are Ancient Egyptian deities?“Some believe to be them, such as the ‘god of all things and gods in his heart.’ In a 2012 article on Archaeology Magazine’s blog about ancient Egypt, William L. Ross described how these two forms evolved from one another…”
3Fluent, confident, and made up. Fine-tuning taught the model the style of the data, not the facts, which is why grounding methods like retrieval matter.
CALUCIO: Not, but you; to medore priend: my stould that dight of mine whom to sting saly him will back; The better never his good the unsare andwar…
4For contrast, a tiny character-level model trained from scratch learns play formatting and spelling patterns, but not real words.
1 / 4
what I found: sampling settings are a real design choice, and a fluent model is not a factual one.
Clothing image classifier
CS 540 · PyTorch
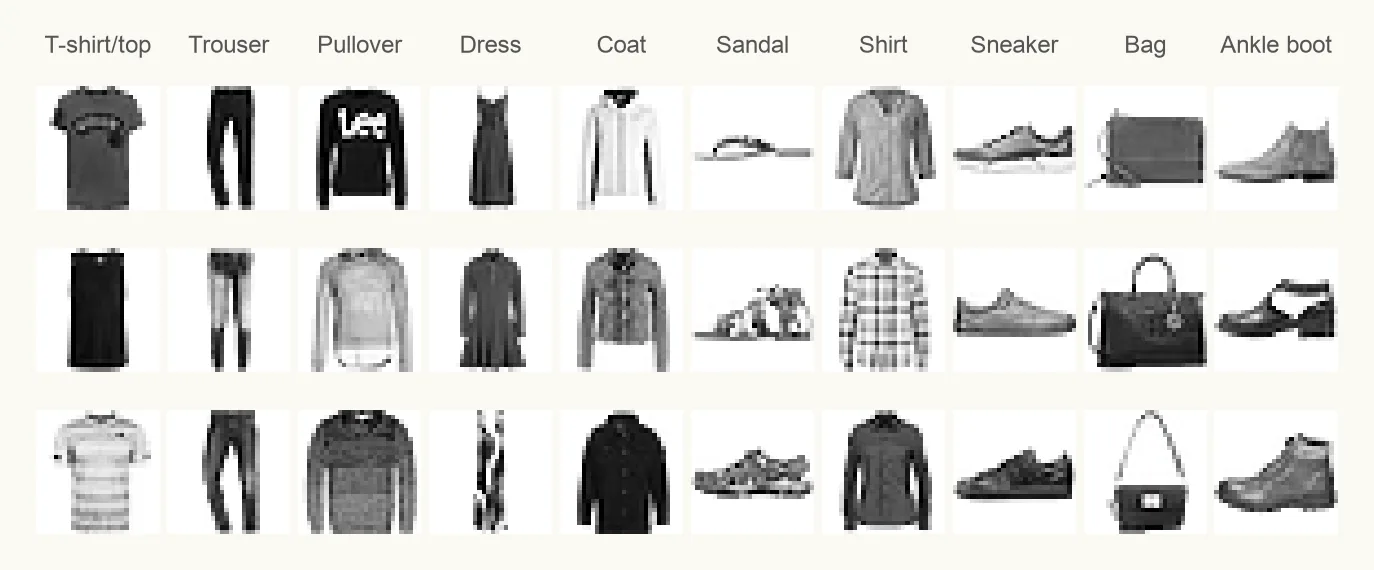
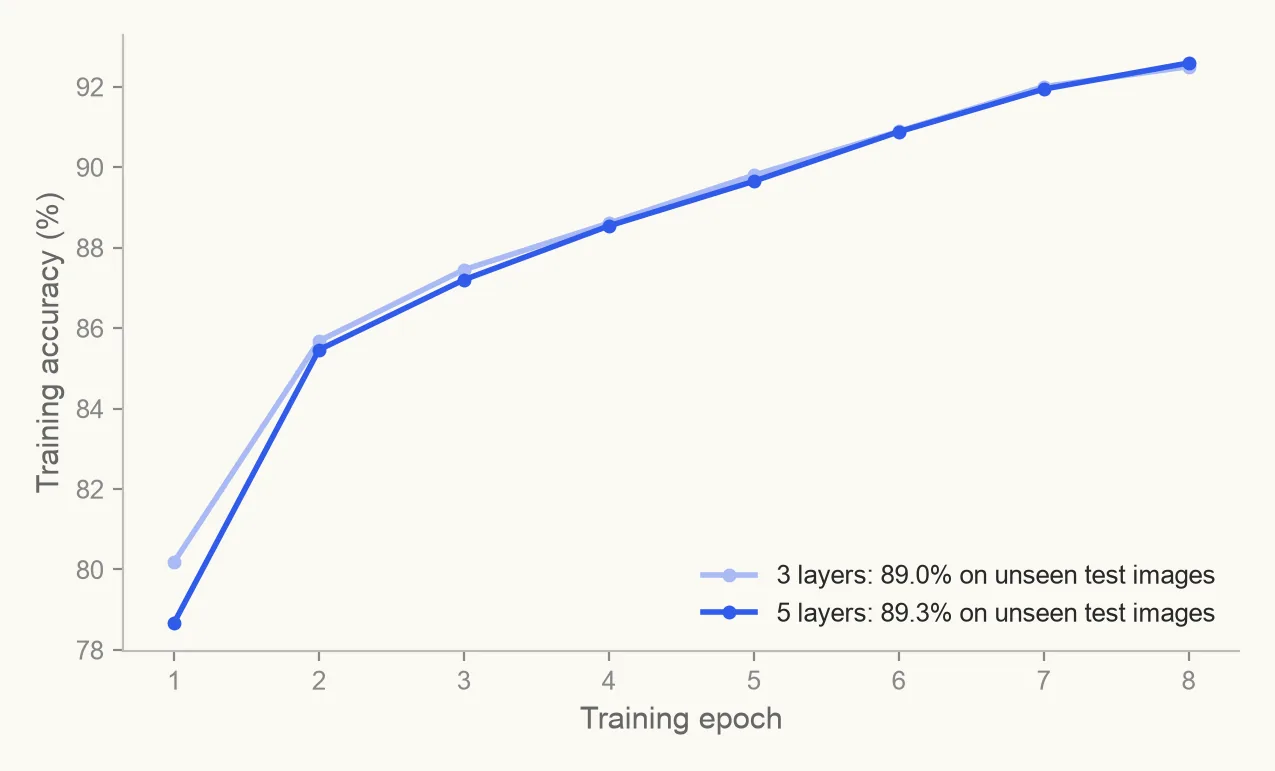
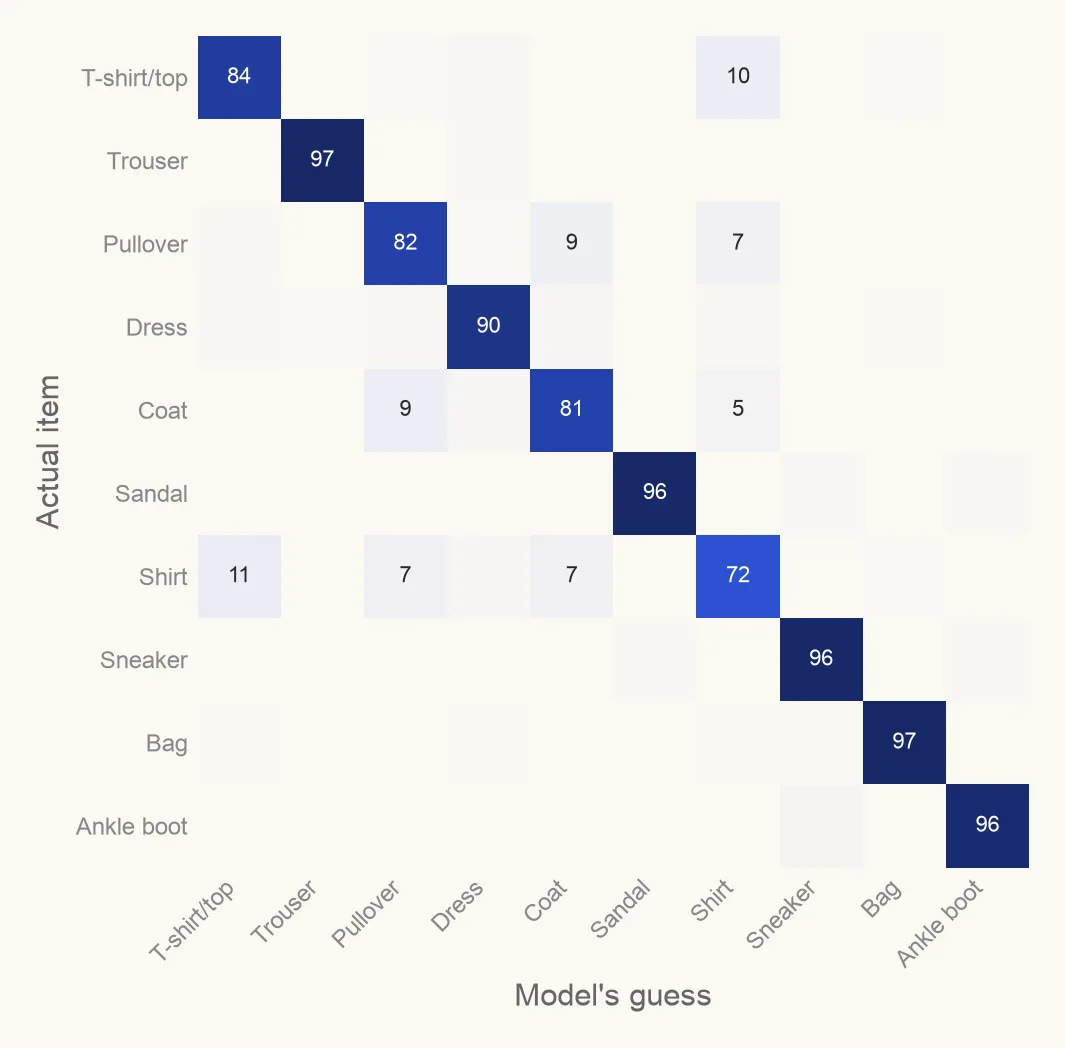
I trained neural networks to recognize 10 kinds of clothing in Fashion-MNIST, comparing a 3-layer and a 5-layer network, then dug into where they still get confused.
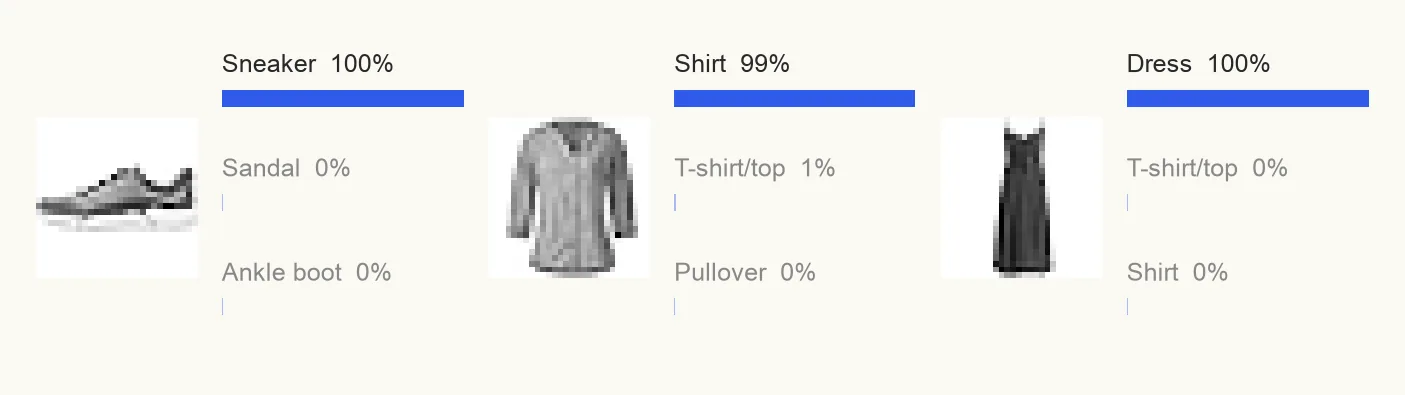
160,000 training images, each 28 × 28 pixels, across 10 classes. I normalized the pixels and fed them in batches of 64.2With an AdamW optimizer and a one-cycle learning-rate schedule, both networks pass 92% on training data and reach 89% on 10,000 images they never saw.3The confusion matrix shows where it struggles. Shirts are right only 72% of the time, and 11% of them get called T-shirts. Honestly, fair.4For any image, the model gives its top three guesses with a confidence for each.
1 / 4
what I found: going deeper barely helped here (89.0% → 89.3%). The remaining errors come from classes that genuinely look alike.
Eigenfaces & a Shakespeare text generator
CS 540 · NumPy
Two from-scratch models. The first is principal component analysis (PCA) that compresses face images into a few numbers. The second is an n-gram model that writes text one character at a time.
PCAeigendecompositionlinear algebraprobabilistic language models
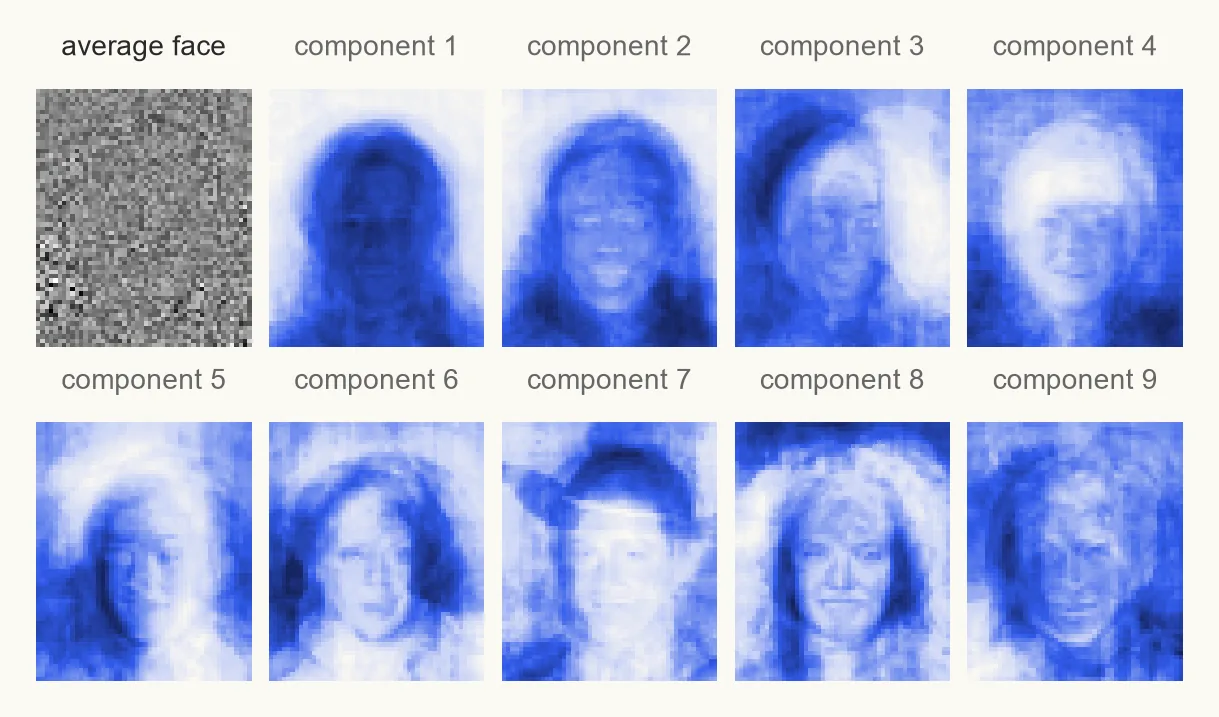
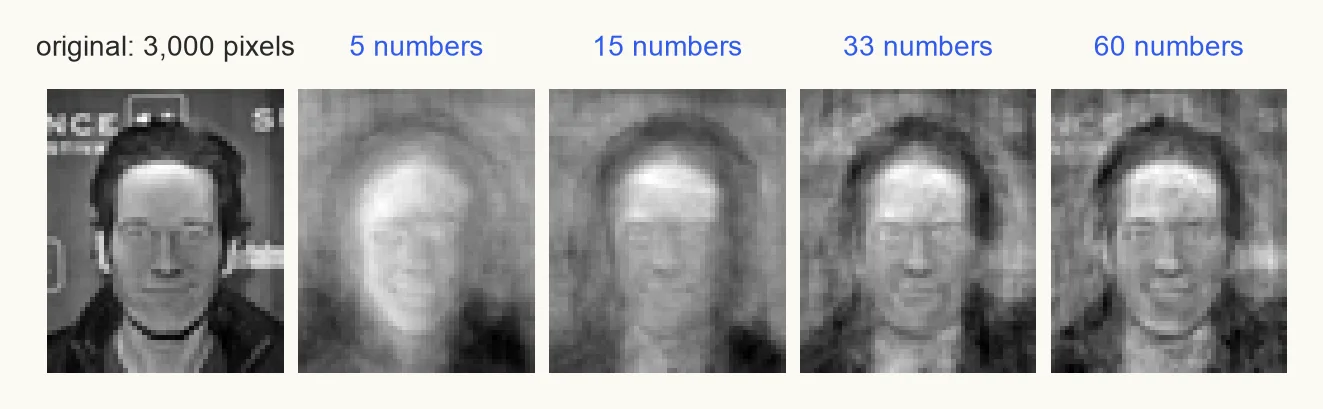
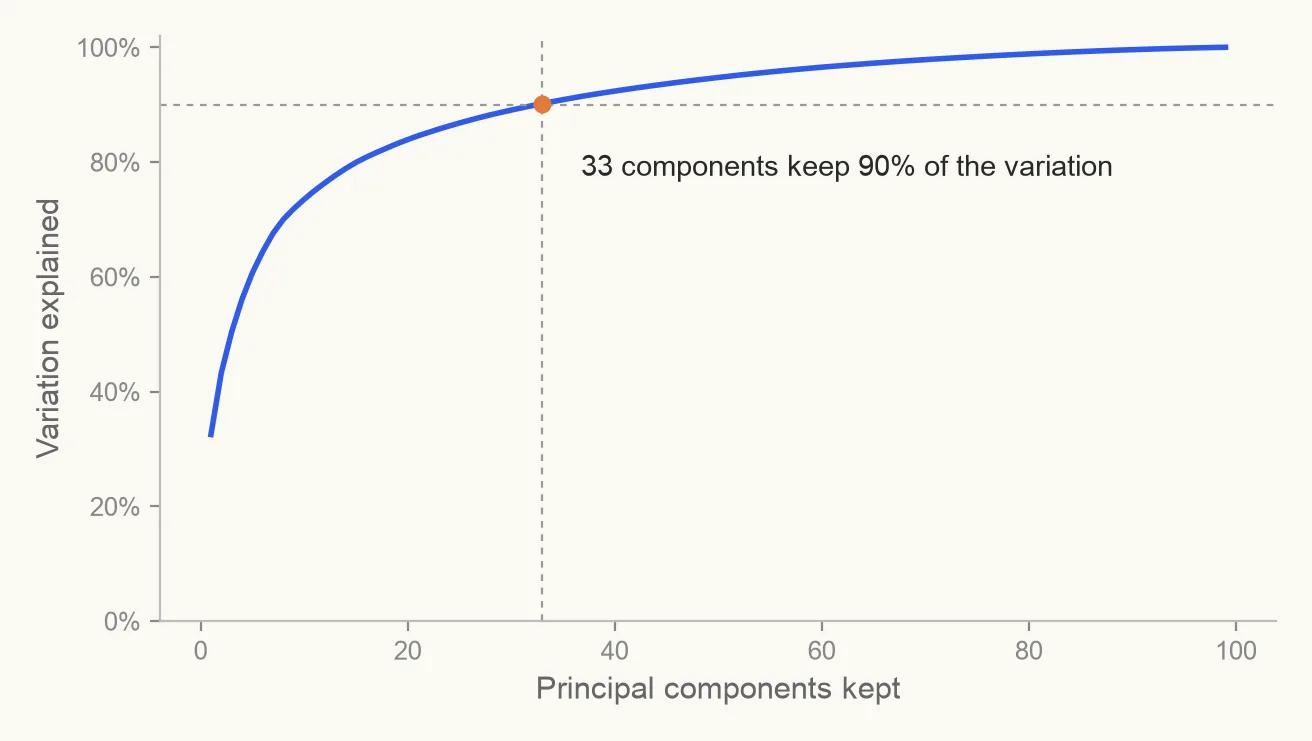
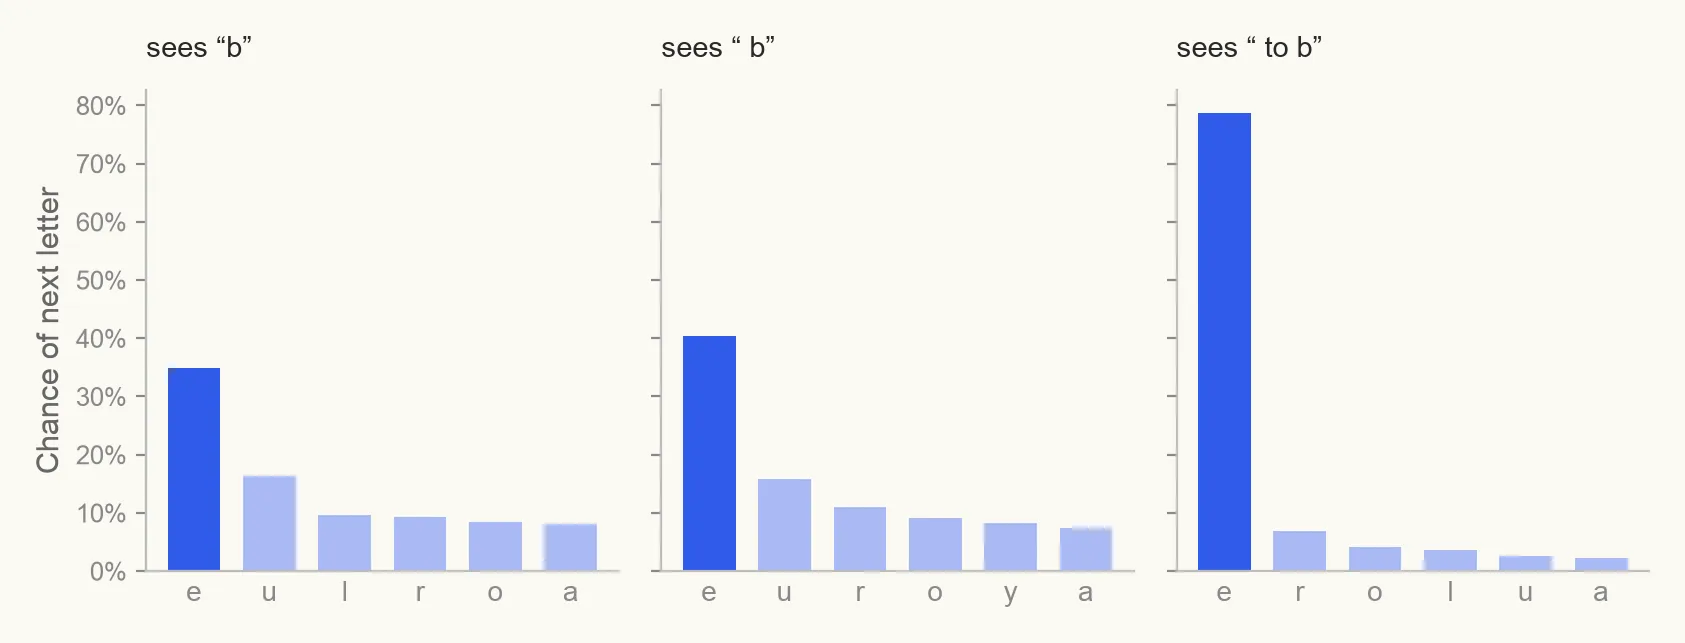
1From 100 faces of 3,000 pixels each, I built the covariance matrix and pulled out its top eigenvectors. These “eigenfaces” capture lighting, hair and face shape.2Any face can be rebuilt as the average face plus a weighted mix of eigenfaces. More components means more detail.3Three components already explain half the variation between faces, and 33 keep 90%. That’s about 1% of the original size.4The text model counts which letter follows each short run of letters in Shakespeare. The more letters it sees, the surer it gets.
2 letters of context“En bowinw t. An ngef I re, imot nesoly hife pres selerung…”
4 letters“Is his holy be their Jack! FALSTAFF. ’Tis Pelian discorrupt…”
7 letters“From whence is nearer that didst well feel your house. Enter Dromio of Syracusian marble hand…”
5Generated text from 1.5 million characters of Shakespeare. With more context, gibberish turns into almost-Shakespeare.
1 / 5
what I found: a lot of high-dimensional data turns out to be simple underneath. A few directions describe most of it.
Clustering the world’s countries
CS 540 · Python
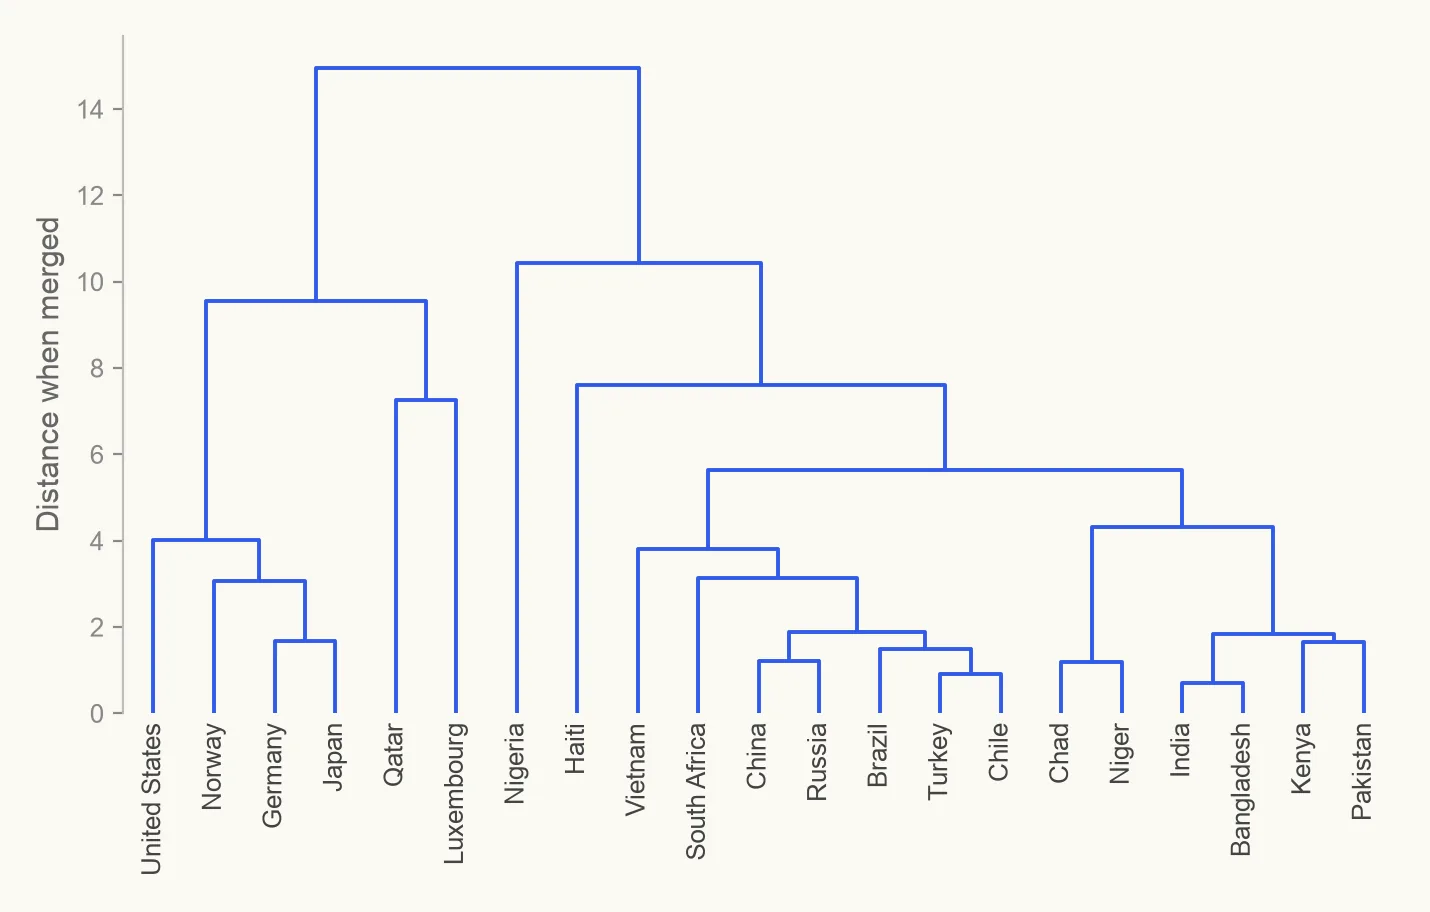
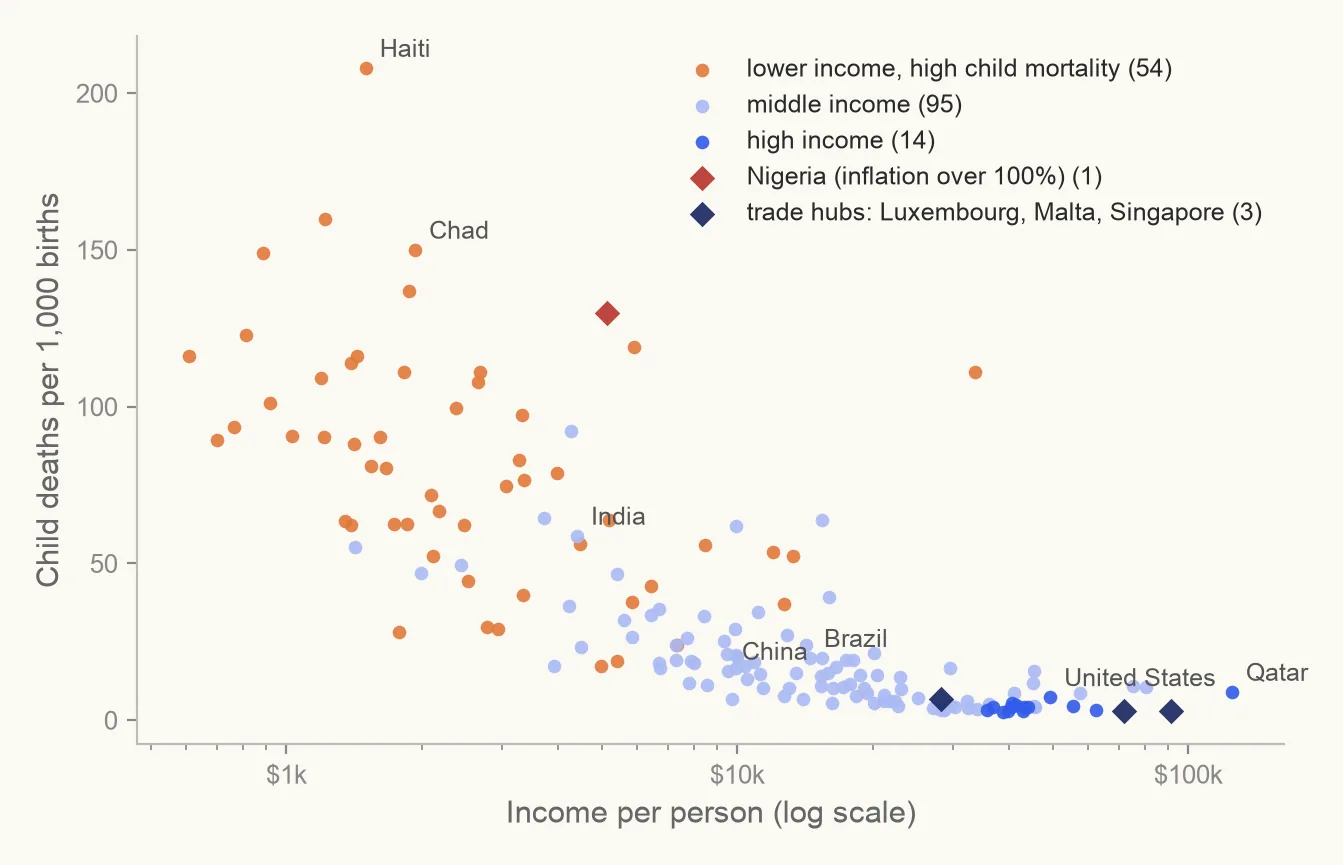
I grouped 167 countries by development data using hierarchical clustering that I implemented myself: it repeatedly merges the two closest groups.
unsupervised learninghierarchical clusteringfeature scalingalgorithms from scratch
167 countries × 9 indicatorschild mortality · exports · health · imports · income · inflation · life expectancy · fertility · GDP per personrescaled so each counts equallymerge the closest pair, 166 times
1The setup. Without rescaling, income (in dollars) would drown out every other measure.2The merge history as a tree, shown for 22 countries. Similar countries join low down, and unusual ones join late.3Cutting the tree into five groups finds income tiers, plus two outlier groups: trade hubs whose trade exceeds their whole economy, and Nigeria, with inflation over 100%.
1 / 3
what I found: the algorithm found both the obvious story (income) and the outliers that don’t fit it.
Data science
What drives battery-service prices in DFW
GEOG 560 · R, GWR
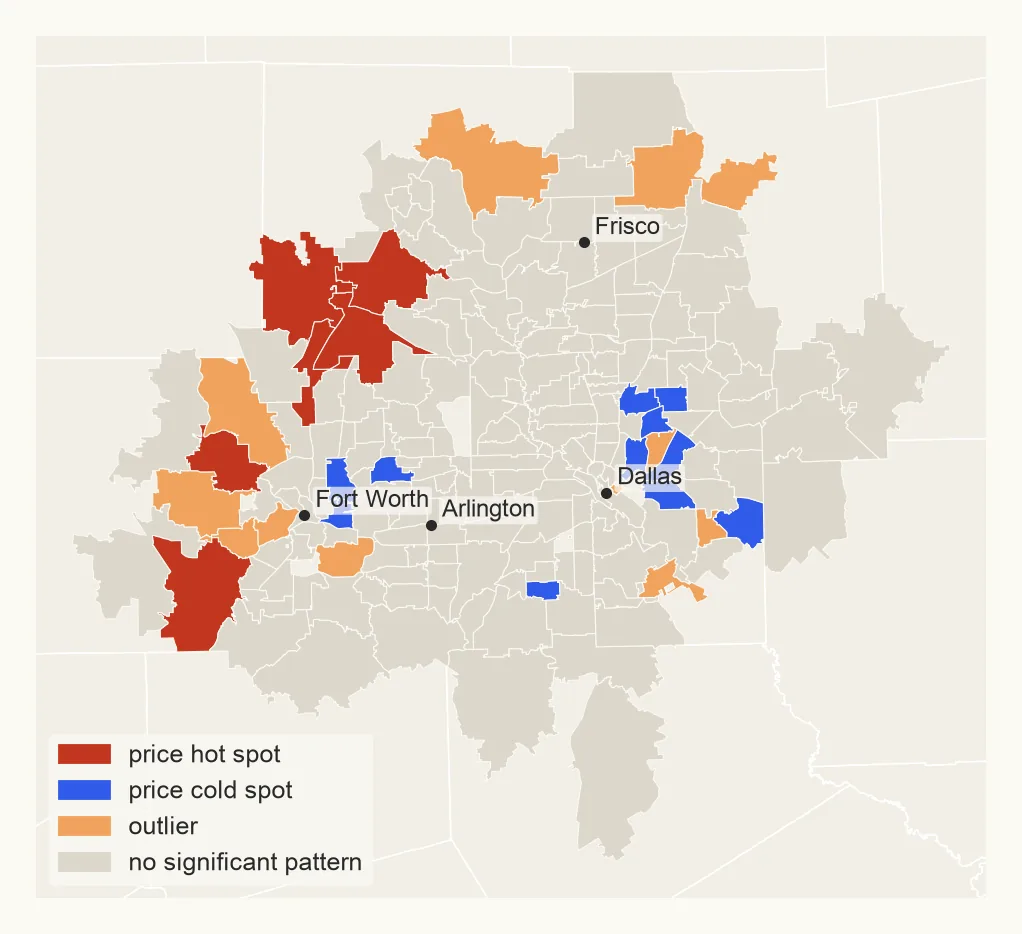
My GEOG 560 final. I joined about 16,000 DIFY service tickets with Census data for roughly 190 Dallas–Fort Worth ZIP areas to test an obvious assumption: that richer neighborhoods pay more. The charts here are a rebuild on 2024 Census data, and the main findings held.
geographically weighted regressionMoran’s I & LISAweighted regressionCensus data
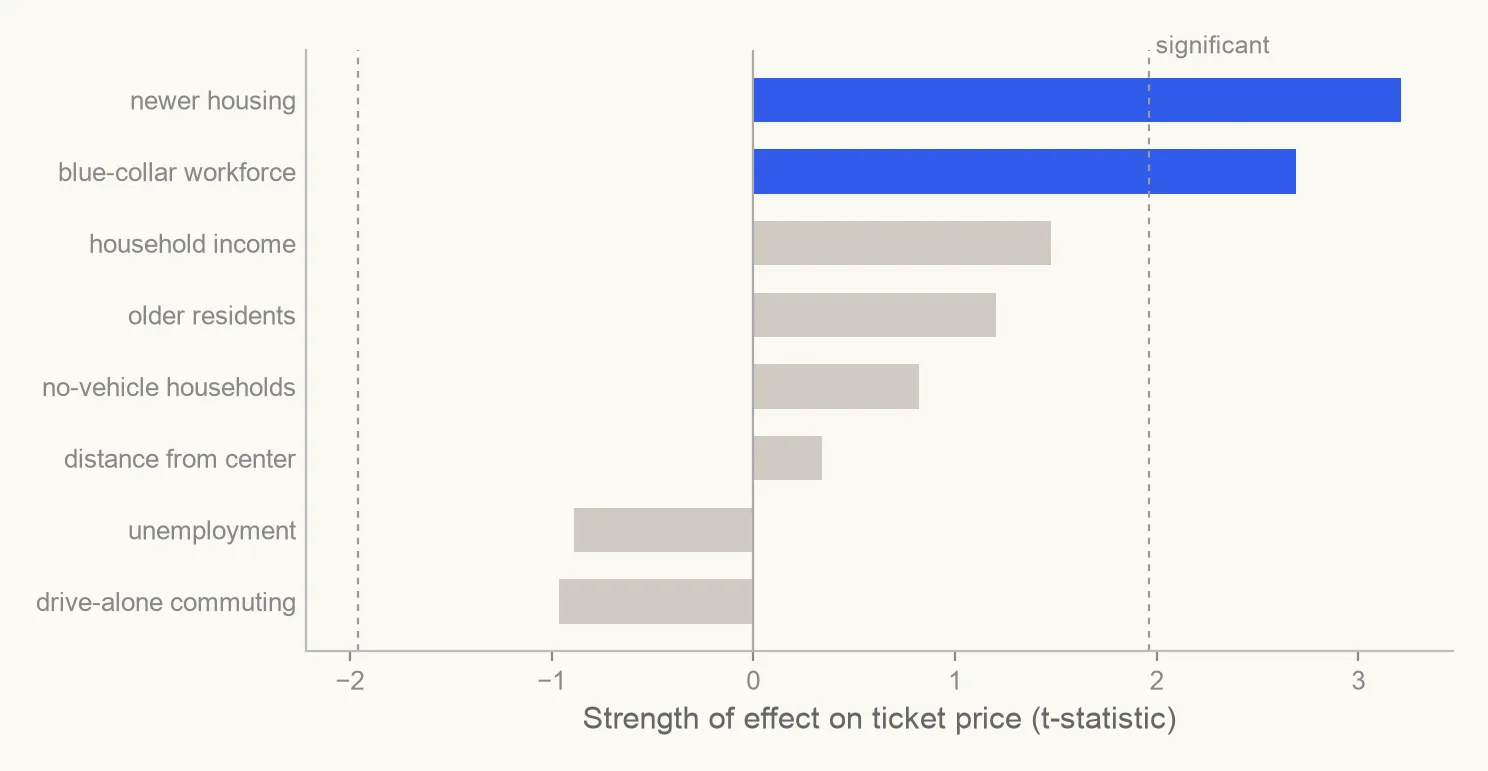
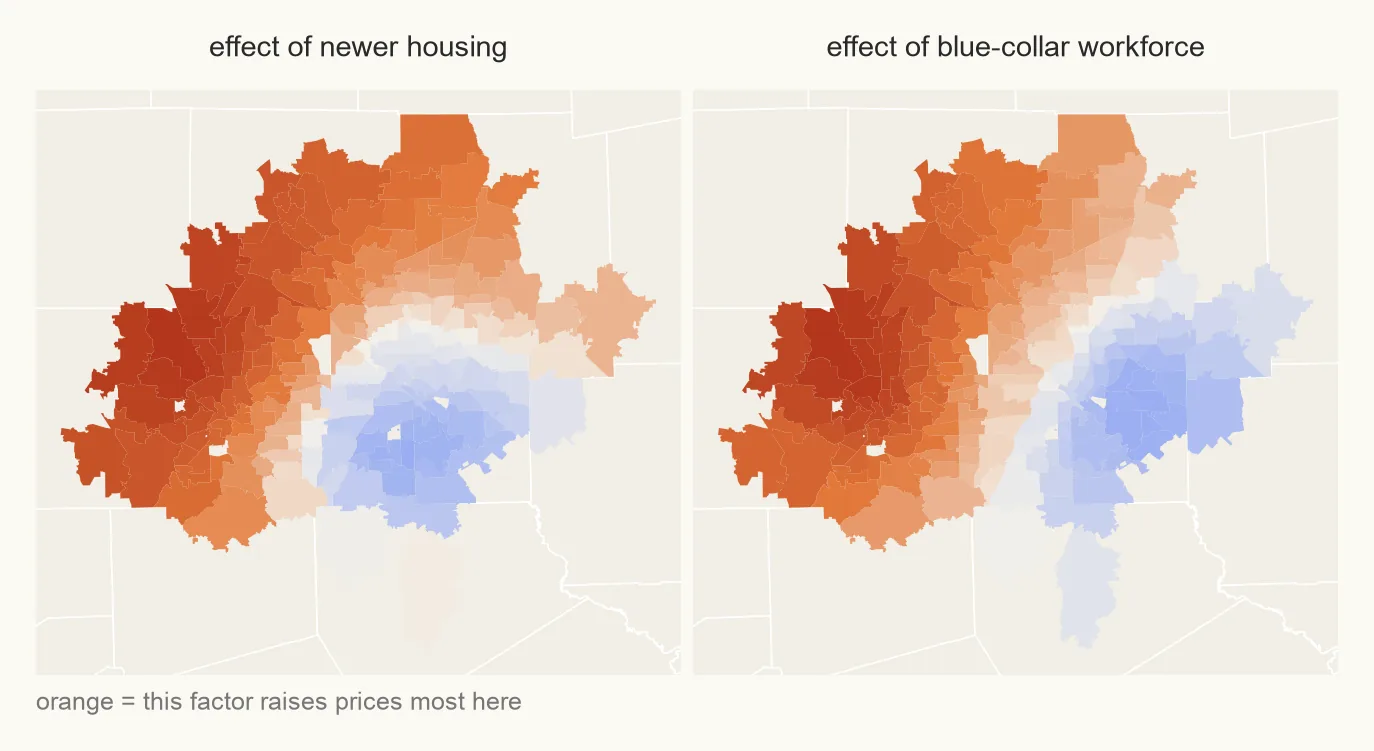
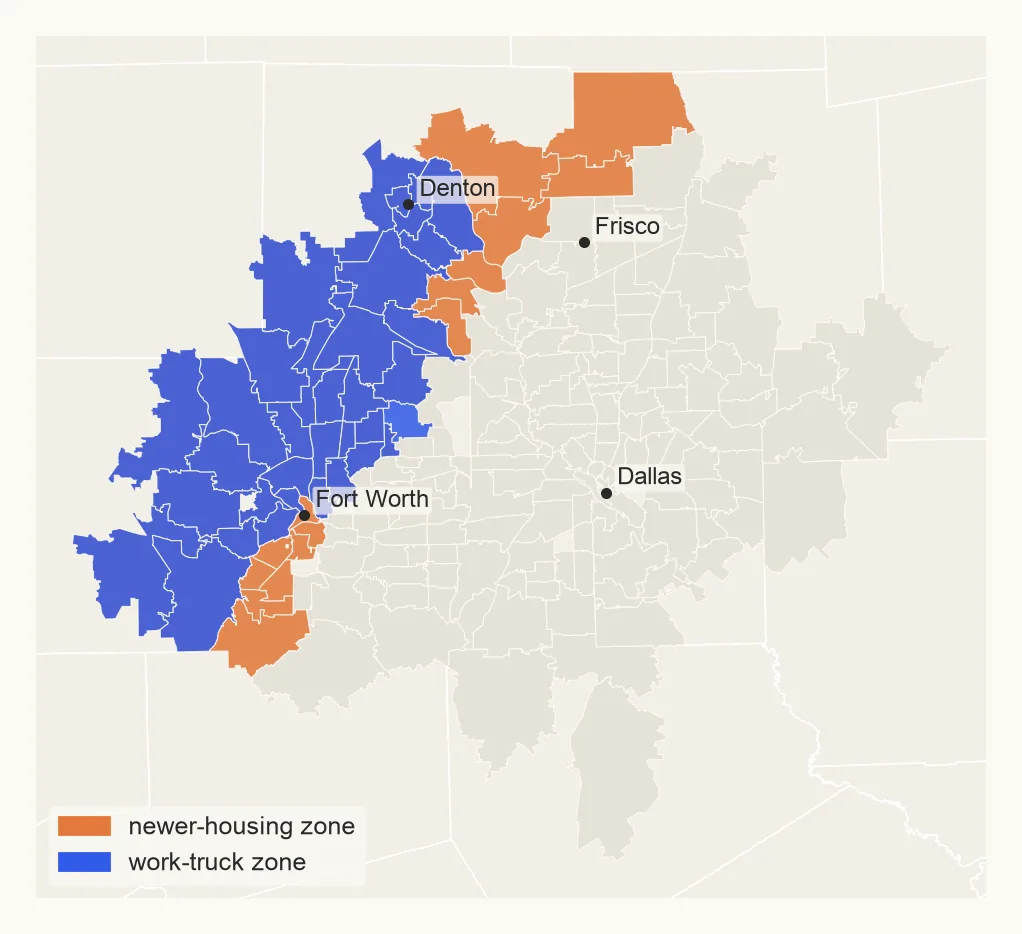
1Average ticket price clusters in space (Moran’s I = 0.14, p = 0.002), with a handful of clear hot and cold spots. Location matters, so a regular regression isn’t enough on its own.2Across eight Census factors, income isn’t significant. Newer housing (newer cars with pricier AGM batteries) and a blue-collar workforce (work trucks, often with two batteries) are.3Geographically weighted regression lets each effect vary by place. Both are strongest on the Fort Worth side and weakest in central Dallas. Going local lifts R² from 0.12 to 0.19.4Action zones are ZIPs where an effect is both statistically reliable and in the top quarter by strength. They became ad strategies: expert AGM installs in one zone type, fast heavy-duty service in the other.
1 / 4
what I found: the obvious hypothesis was wrong. What people drive, not what they earn, sets the price.
Where to launch next: screening Phoenix
DIFY Battery · Python, R
Before DIFY expanded to Phoenix, I built a model that learns what drives demand in Austin, Dallas–Fort Worth and Houston, then scores all 127 Phoenix ZIP areas. It combines a year of completed jobs (tens of thousands of calls) with Census, workplace, local business and NOAA weather data.
leave-one-market-out validationridge regressionfeature engineeringCensus · LODES · ZBP data
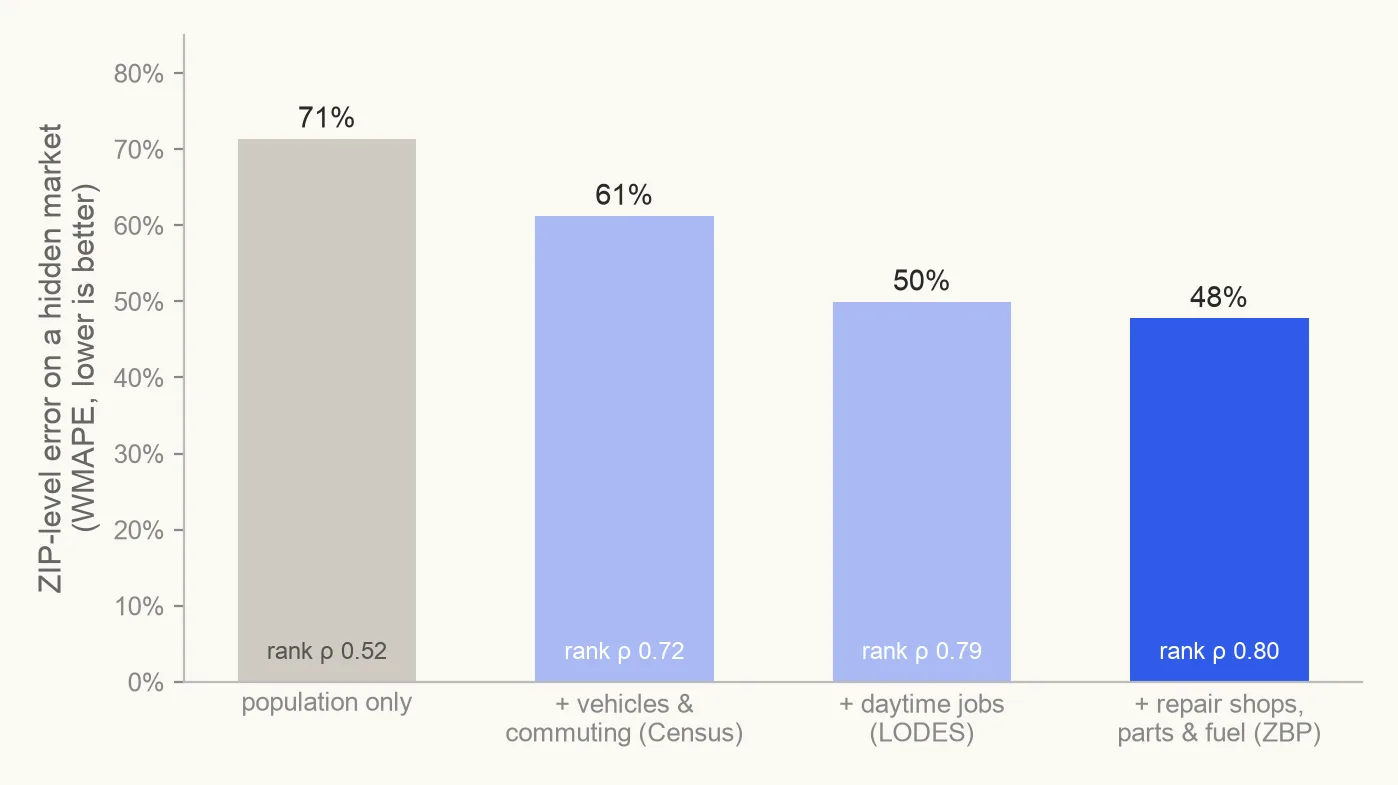
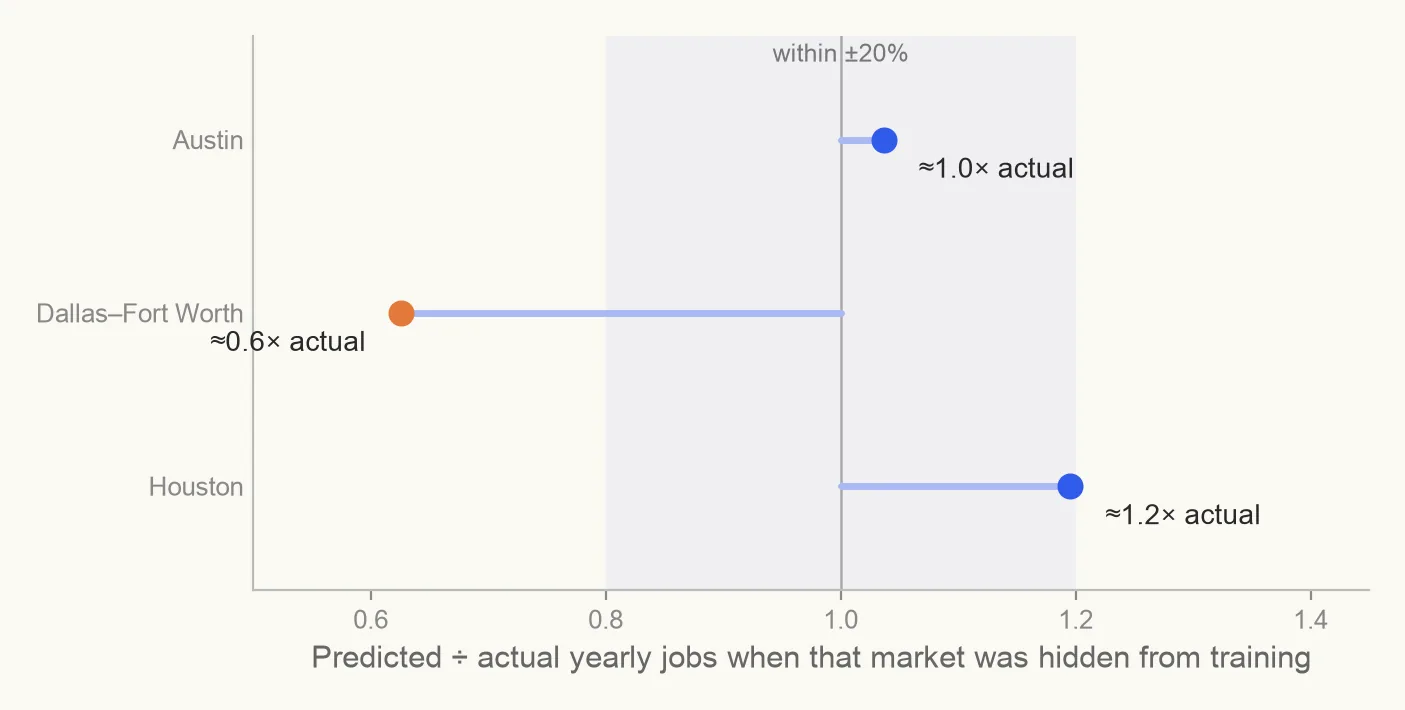
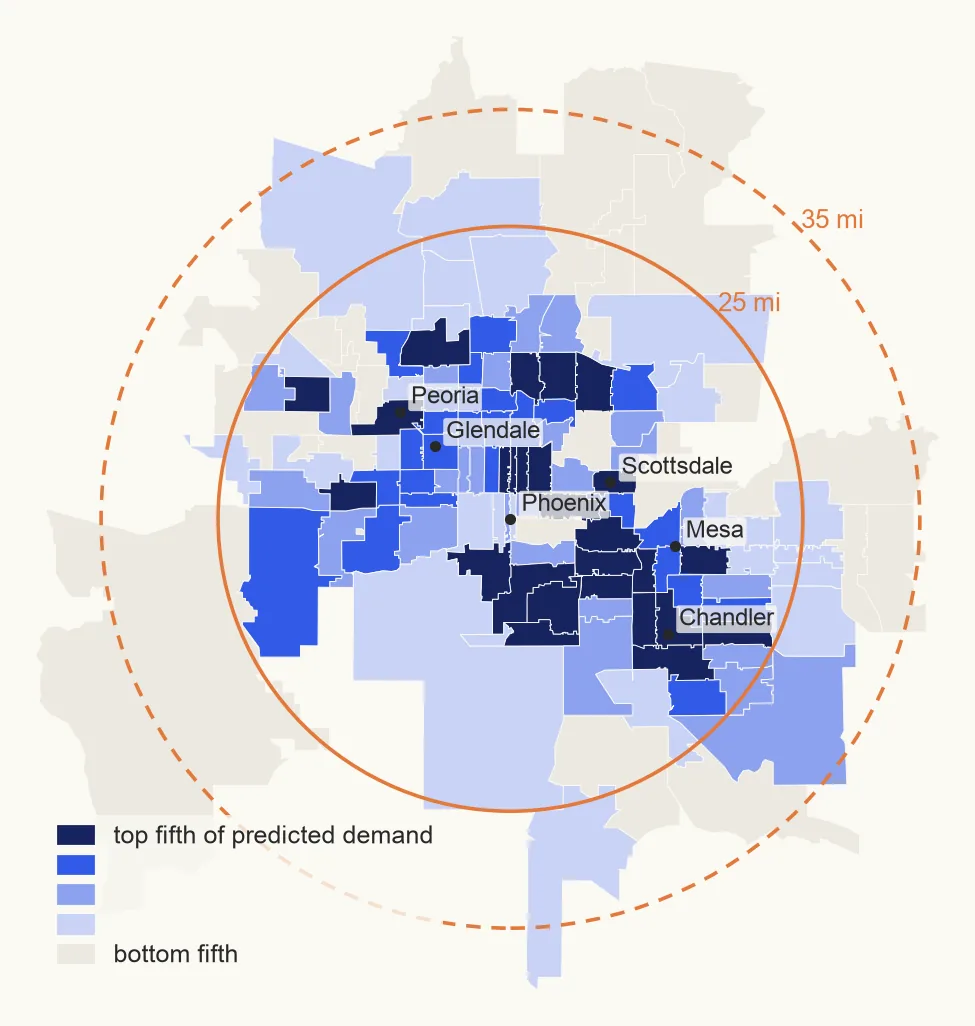
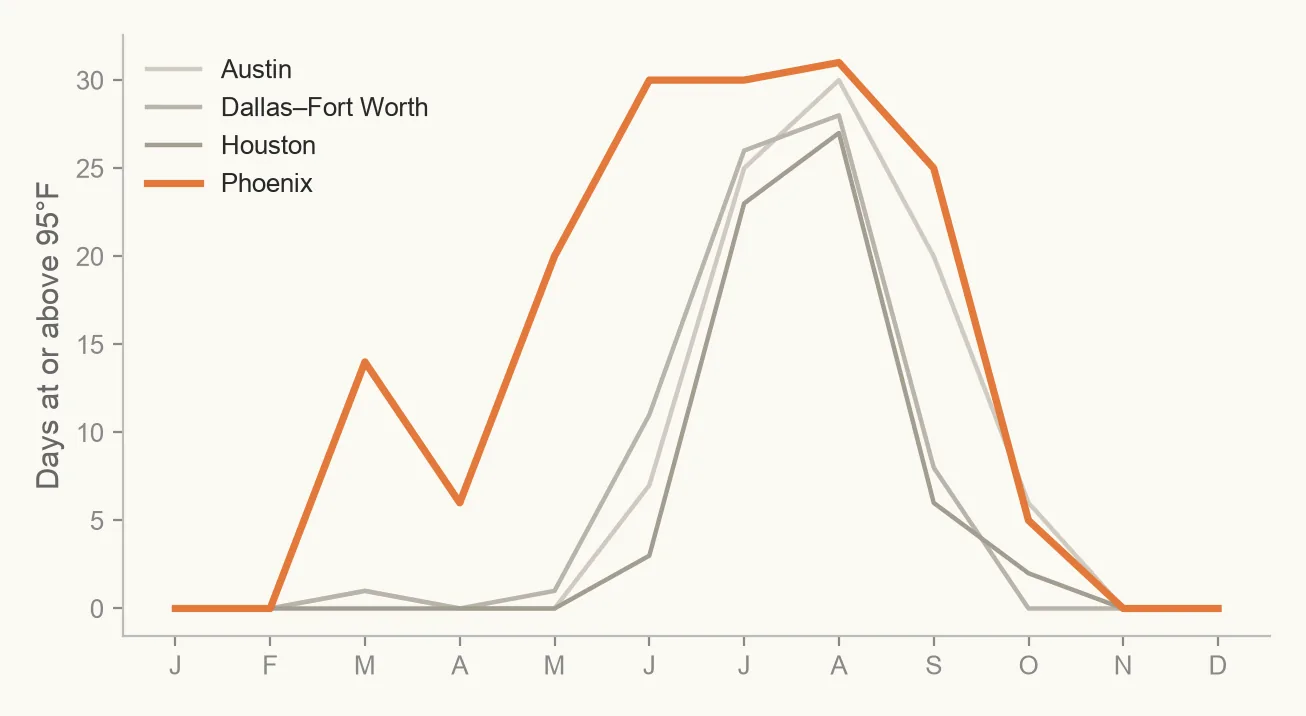
1To test it, I hid one Texas market at a time and predicted it ZIP by ZIP. Knowing where people work gave the biggest gain. Error fell from 71% to 48%, and ranking accuracy rose to 0.80.2Totals are harder than rankings. Austin landed close, Houston about 20% high, and Dallas–Fort Worth roughly a third low, so I report volume as a range, not a single number.3The Phoenix screen, led by Scottsdale, Chandler and Tempe ZIPs. About 95% of predicted demand falls within 25 miles, which became the recommended pilot area.4In Texas, hot stretches predict more calls over the following days, a small but consistent out-of-time gain. Phoenix had 161 days above 95°F last year, so I treat heat as an upside scenario, not a promise.
1 / 4
what I found: the model is good at ranking where to start, not at promising revenue, so the plan is a staged 25-mile pilot with clear go/no-go checks.
Where poverty clusters in the US
GEOG 560 · GeoPandas, PySAL
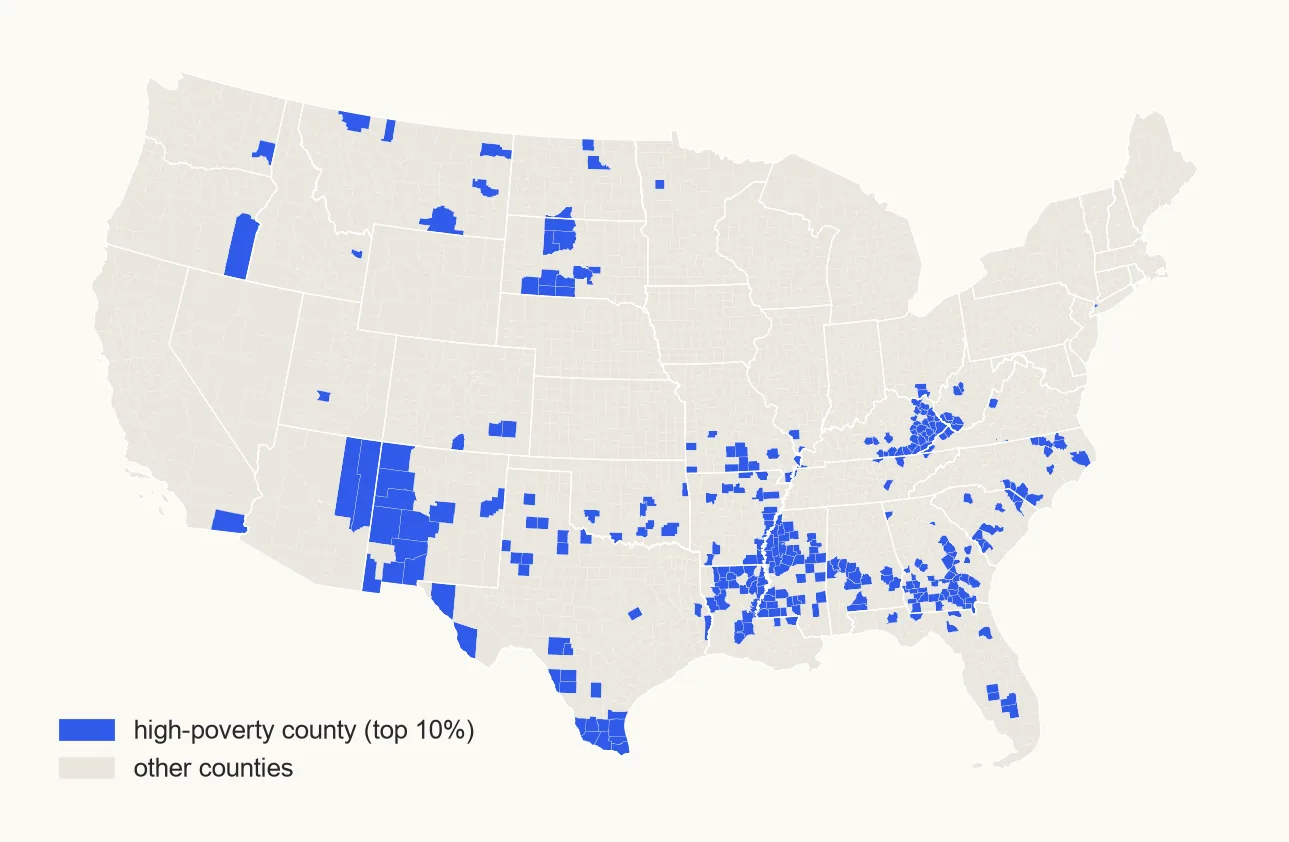
Using the CDC’s Social Vulnerability Index, I mapped high-poverty counties, tested whether they cluster geographically, and tried to predict them from other county data.
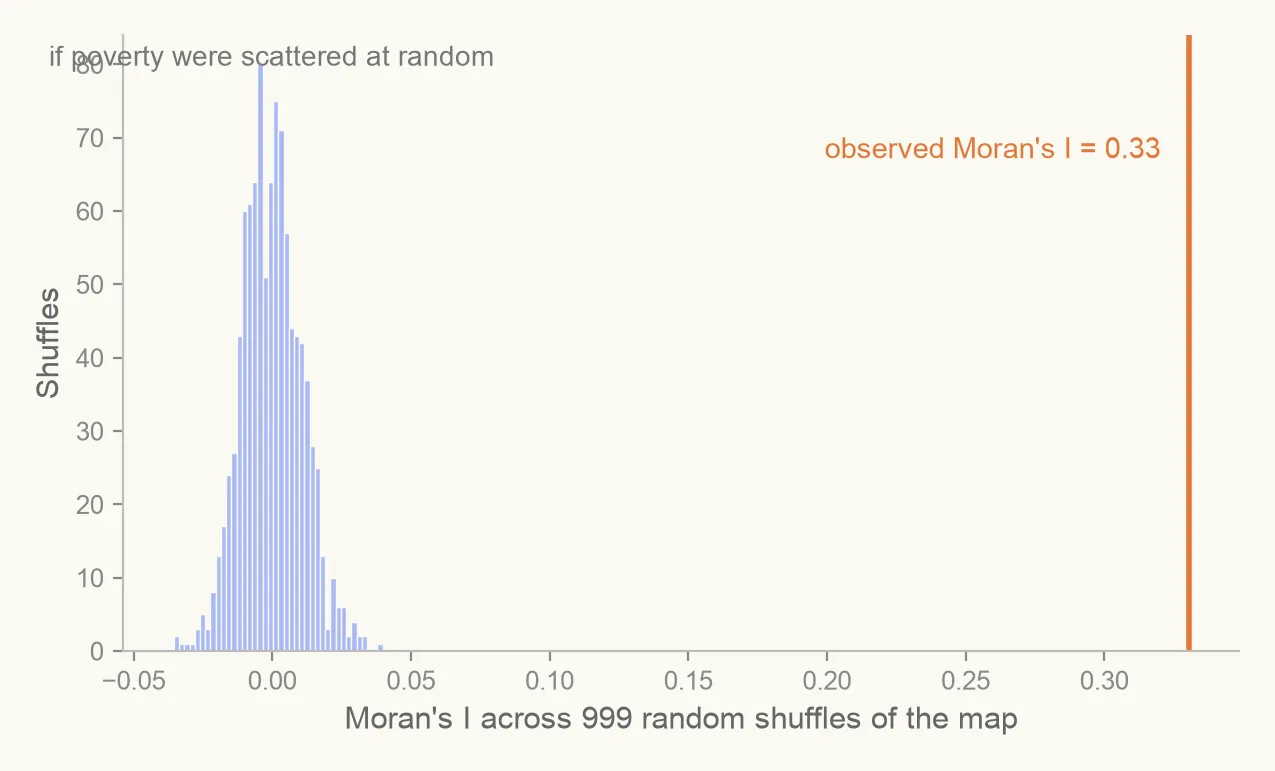
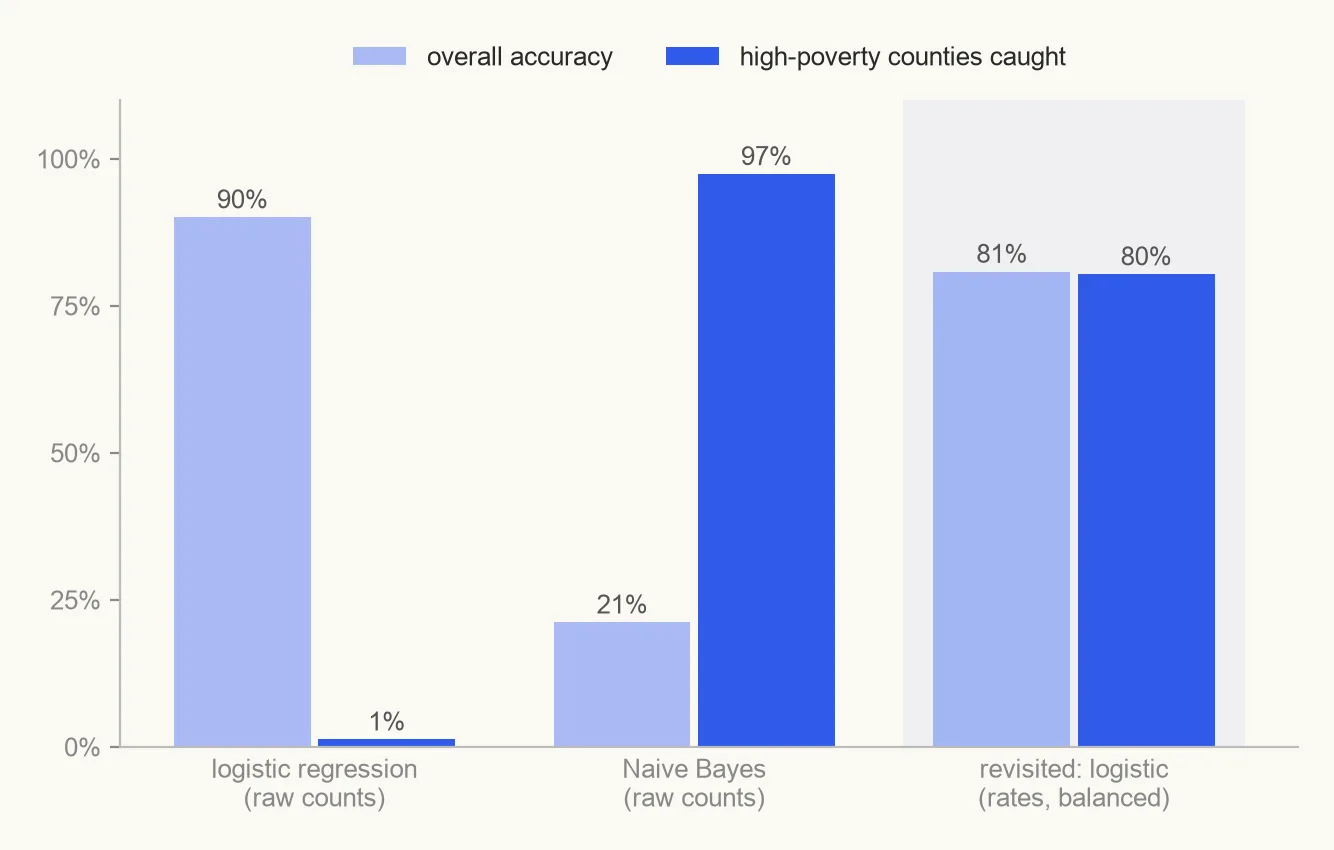
1307 of 3,109 counties are flagged high-poverty. They’re not scattered: they concentrate in the Delta, Appalachia, tribal lands and the border.2Moran’s I puts a number on it. I shuffled the map 999 times, and none came close to the real clustering (I = 0.33, p = 0.001).3The accuracy trap. My first model scored 90%, which sounds great until you notice it almost never flagged a county. Revisiting it later, switching raw counts to per-person rates and balancing the classes caught 80% of high-poverty counties.
1 / 3
what I found: location matters, and accuracy alone can hide a model that’s useless for the cases you care about.
Predicting Wisconsin’s population
CS 320 · GeoPandas, SQL, rasterio
I joined census data from a SQLite database with county shapes and satellite land-cover data, then built regression models that predict population.
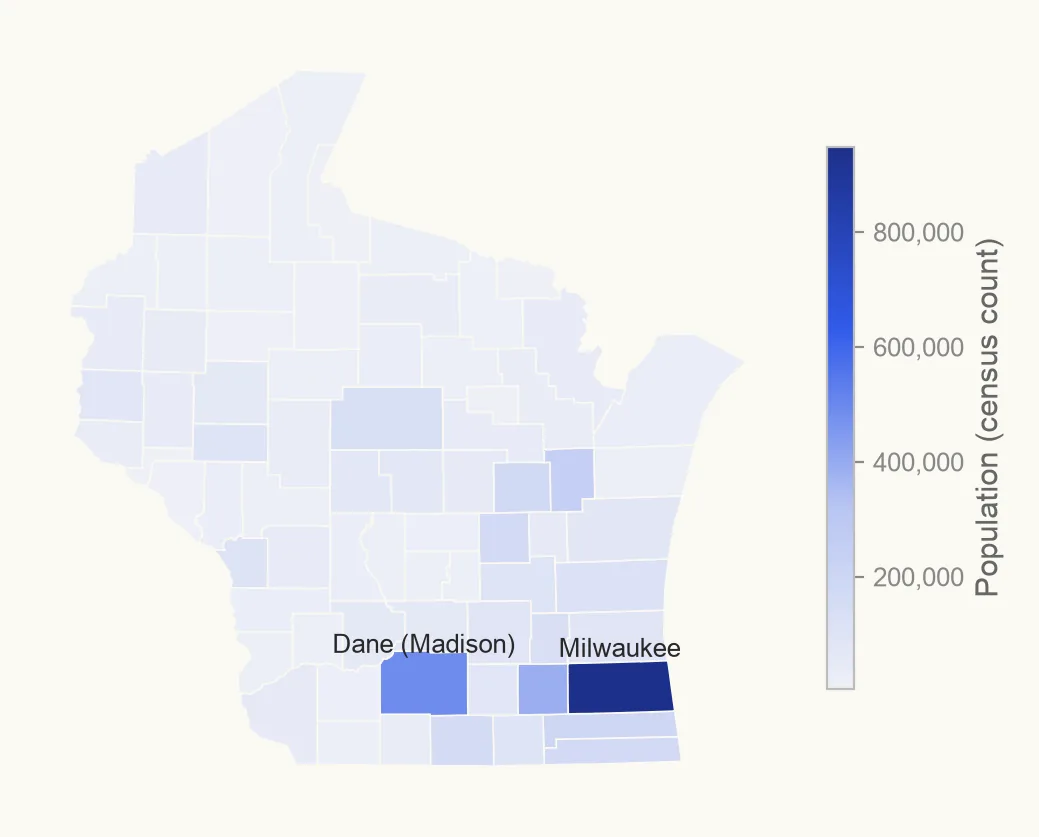
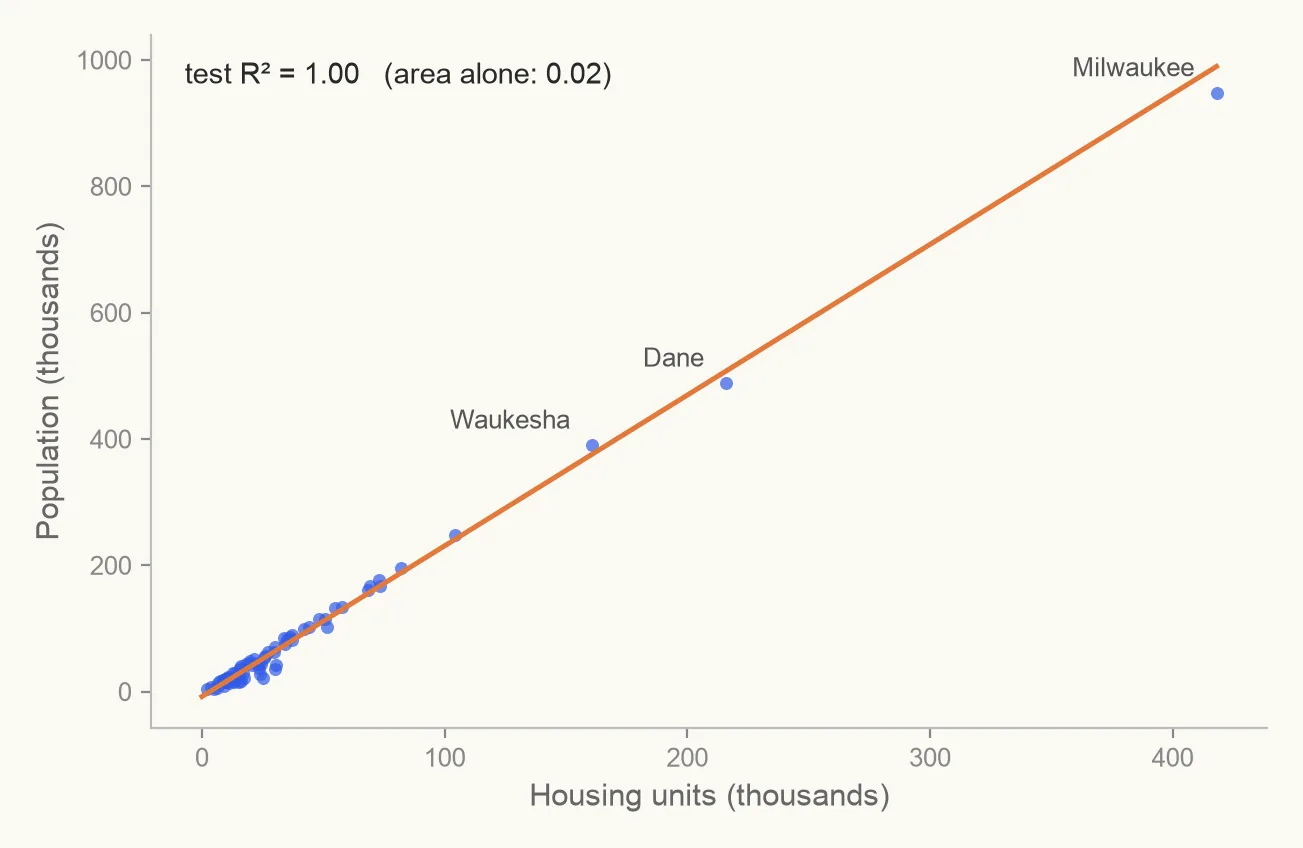
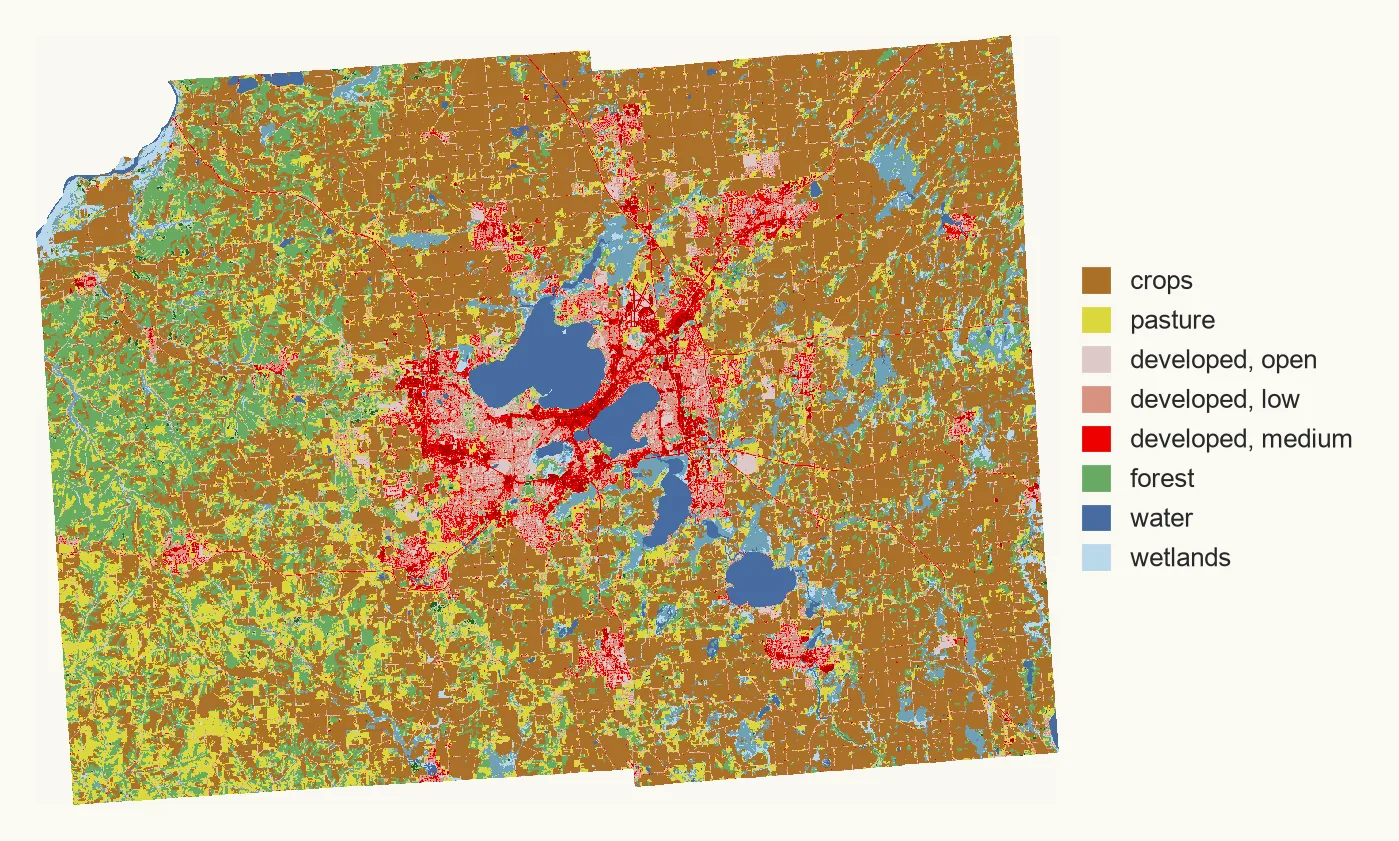
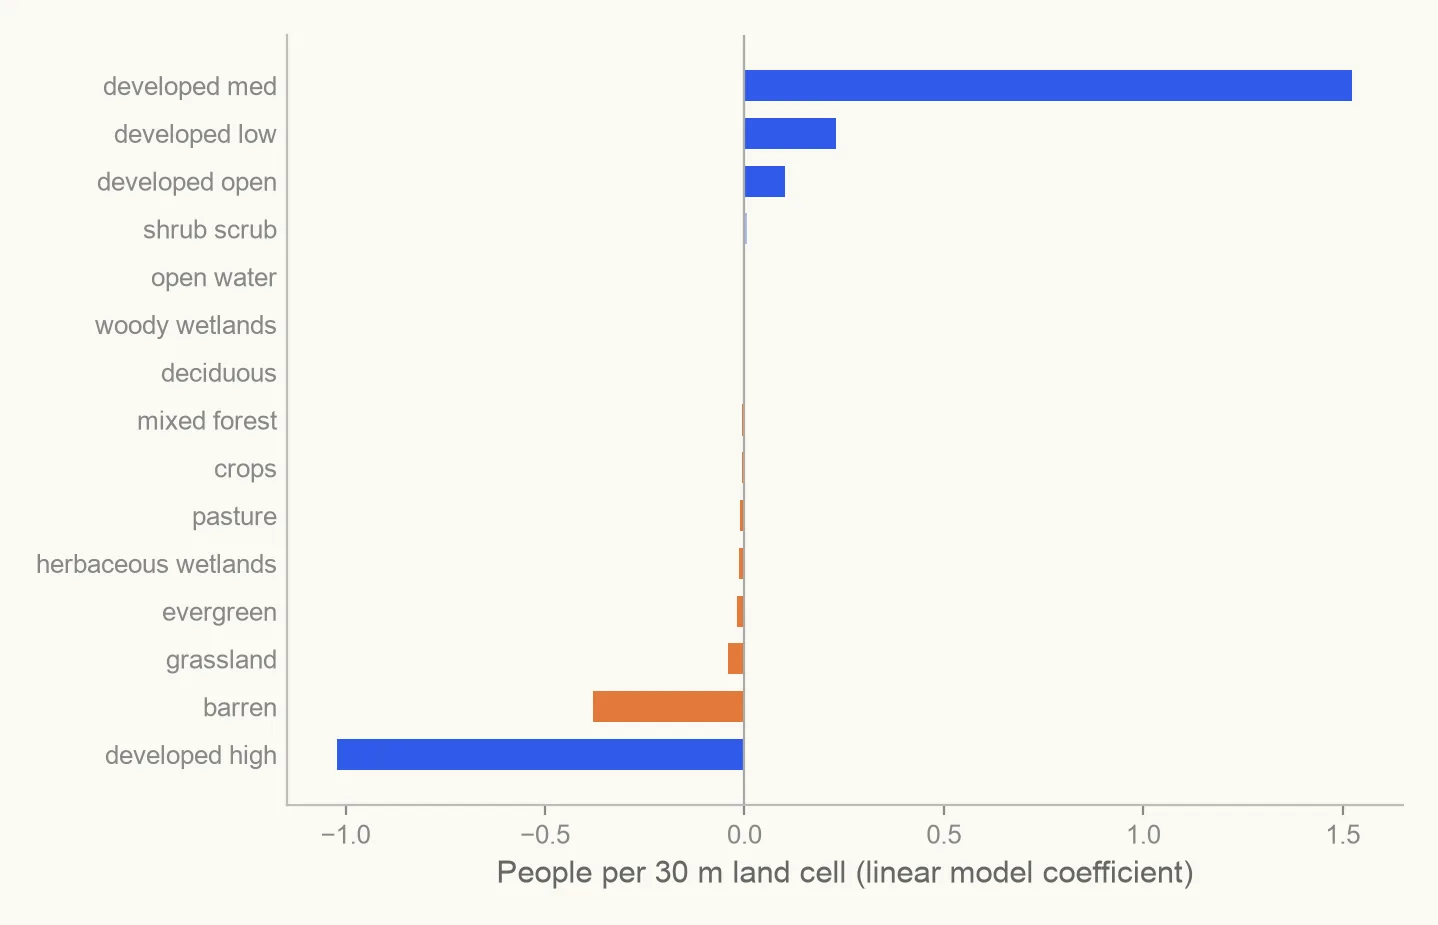
1Wisconsin’s 72 counties by population. Milwaukee and Dane stand far above the rest.2Land area predicts almost nothing (R² = 0.02). Housing units, summed from tract-level SQL, predict population almost perfectly: R² = 0.996 on held-out counties.3Cropping satellite land-cover data to each area’s boundary. Dane County is 47% cropland, with Madison’s development wrapped around the lakes.4Across 1,542 census tracts, I counted each land-cover type and let a model weigh them. Developed land drives the prediction (cross-validated R² ≈ 0.52).
1 / 4
what I found: the right feature beats a clever model. Housing units alone explain almost everything at the county level.
House prices
Lab · scikit-learn
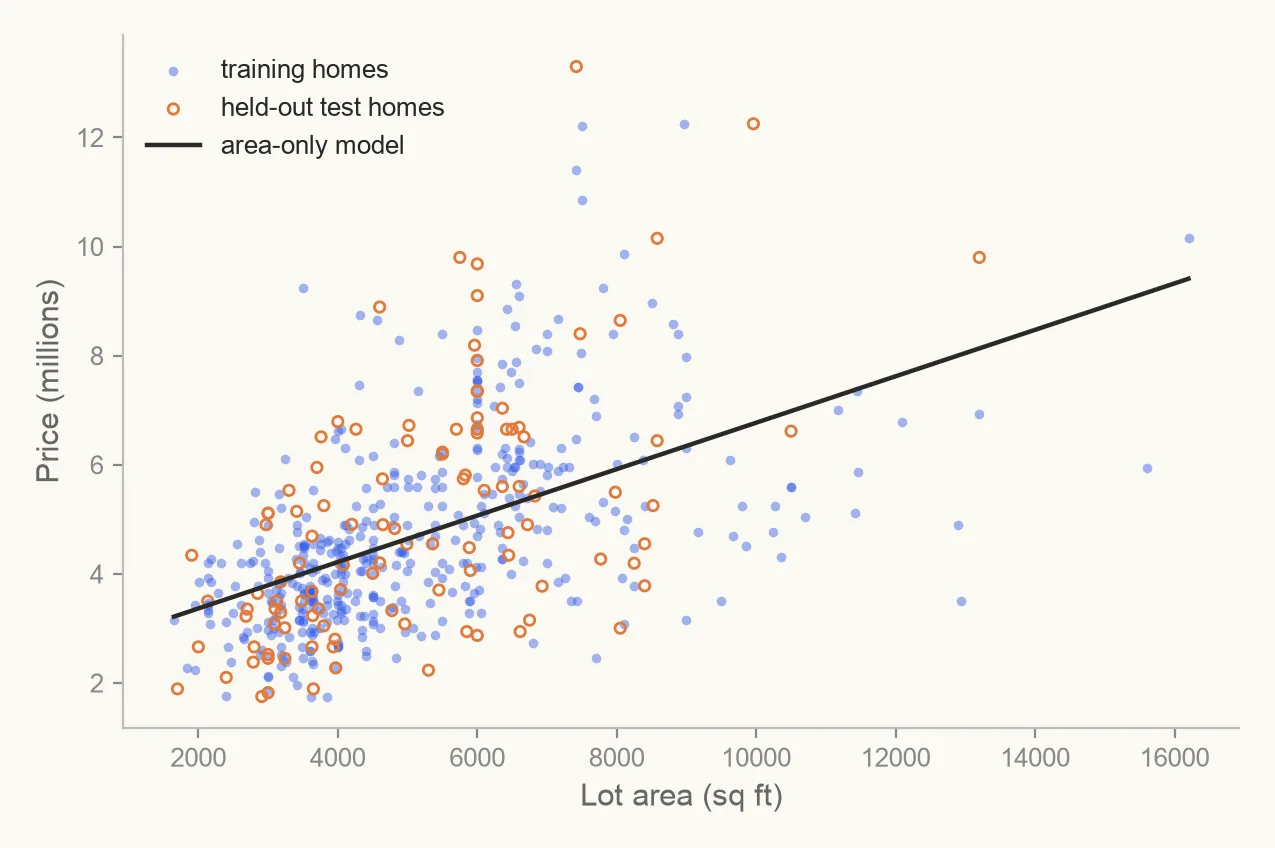
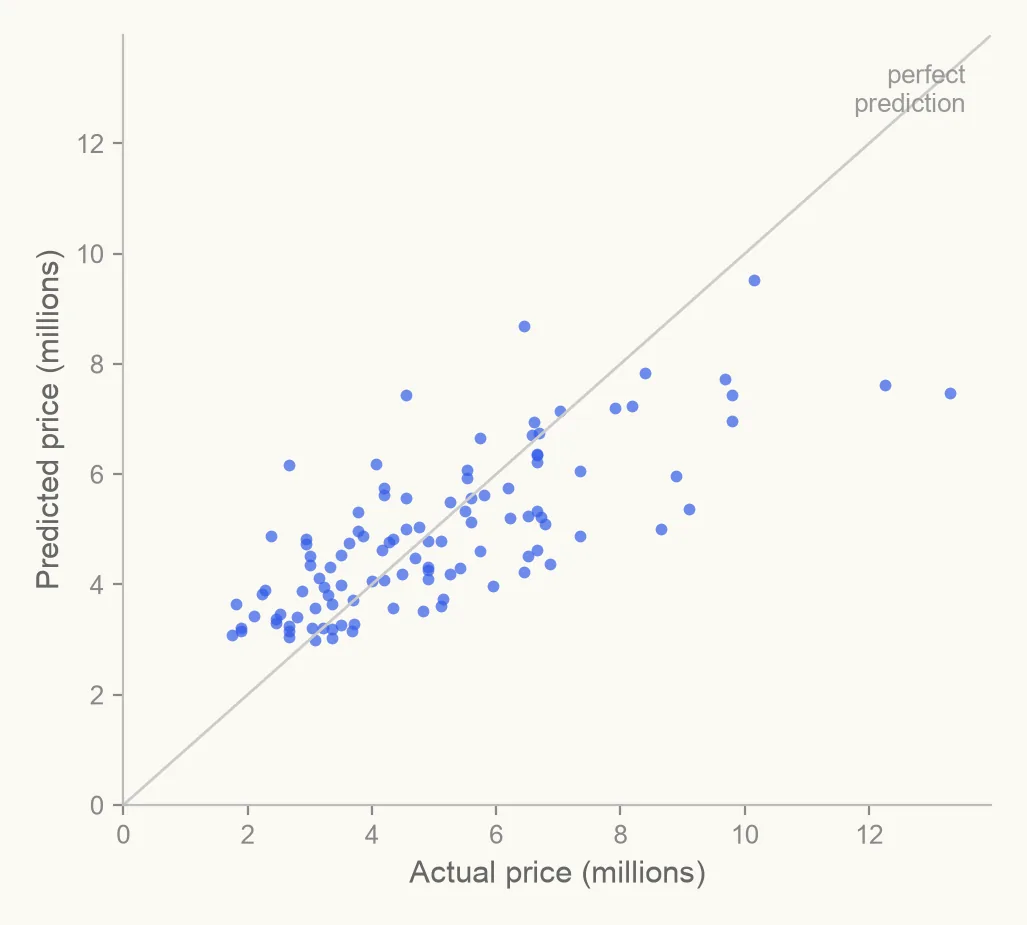
Predicting house prices from 545 listings, starting with a single feature and measuring how much each addition helps on homes the model hasn’t seen.
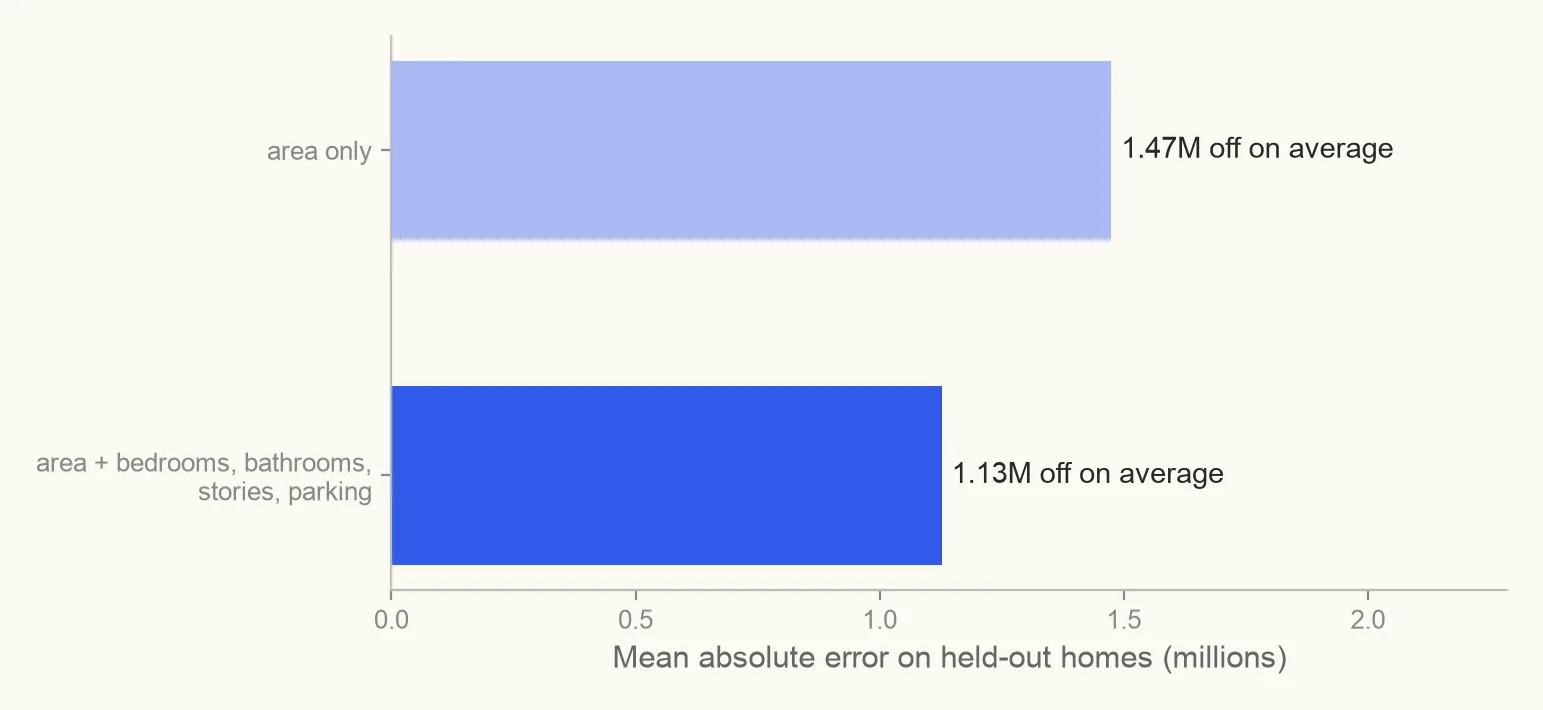
1I held out 20% of homes before fitting anything. Area alone gives a rough upward trend, with a lot of spread.2Adding bedrooms, bathrooms, stories and parking cut the average error by 24% on held-out homes.3Predicted against actual. The model is solid mid-market but undershoots expensive homes, a sign it’s missing features like location.
1 / 3
what I found: always judge a model on data it hasn’t seen, and read the residuals, not just the score.
Lake Mendota is losing its ice
CS 540 · NumPy, PyTorch
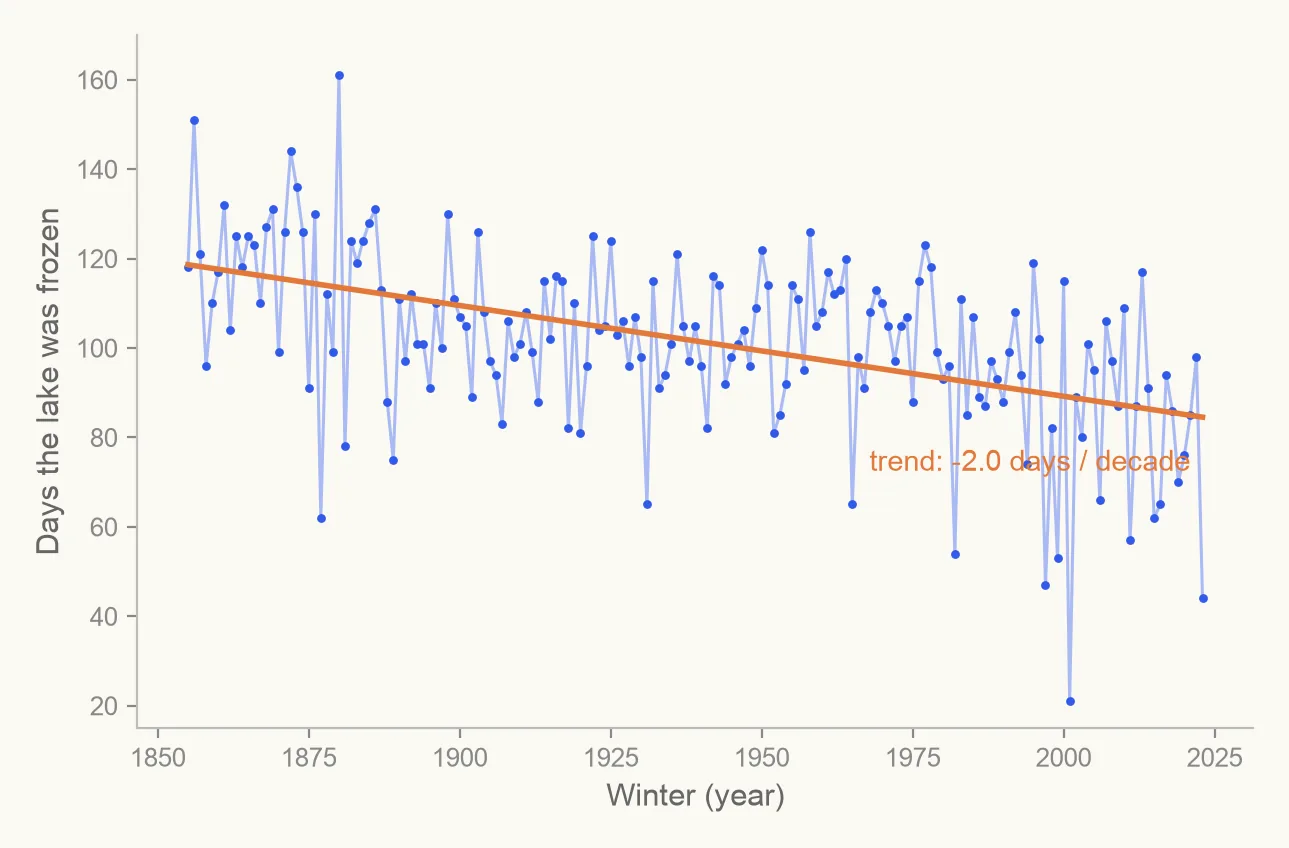
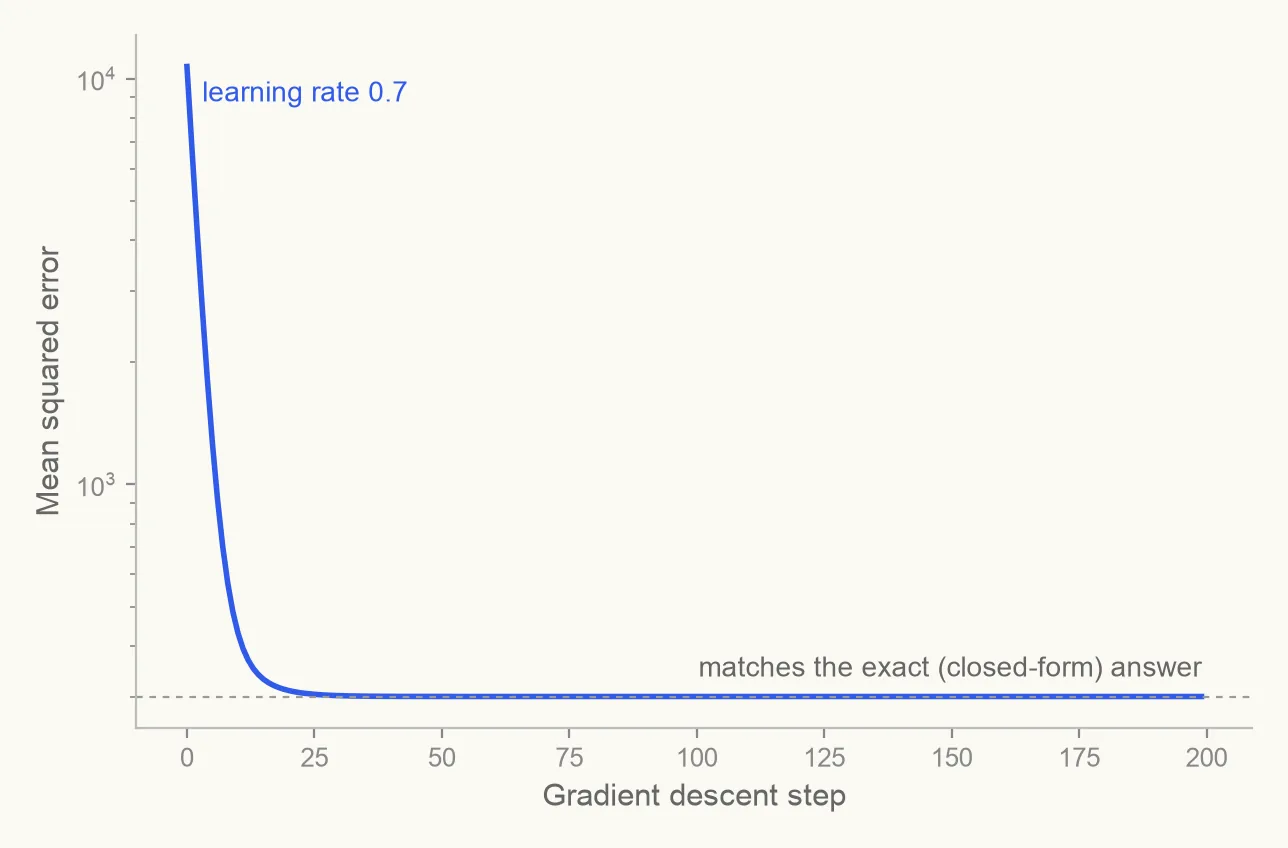
Using 169 winters of ice records for the lake next to campus, I fit a trend two ways: an exact closed-form solution, and gradient descent written with PyTorch.
linear regressiongradient descentnormalizationextrapolation
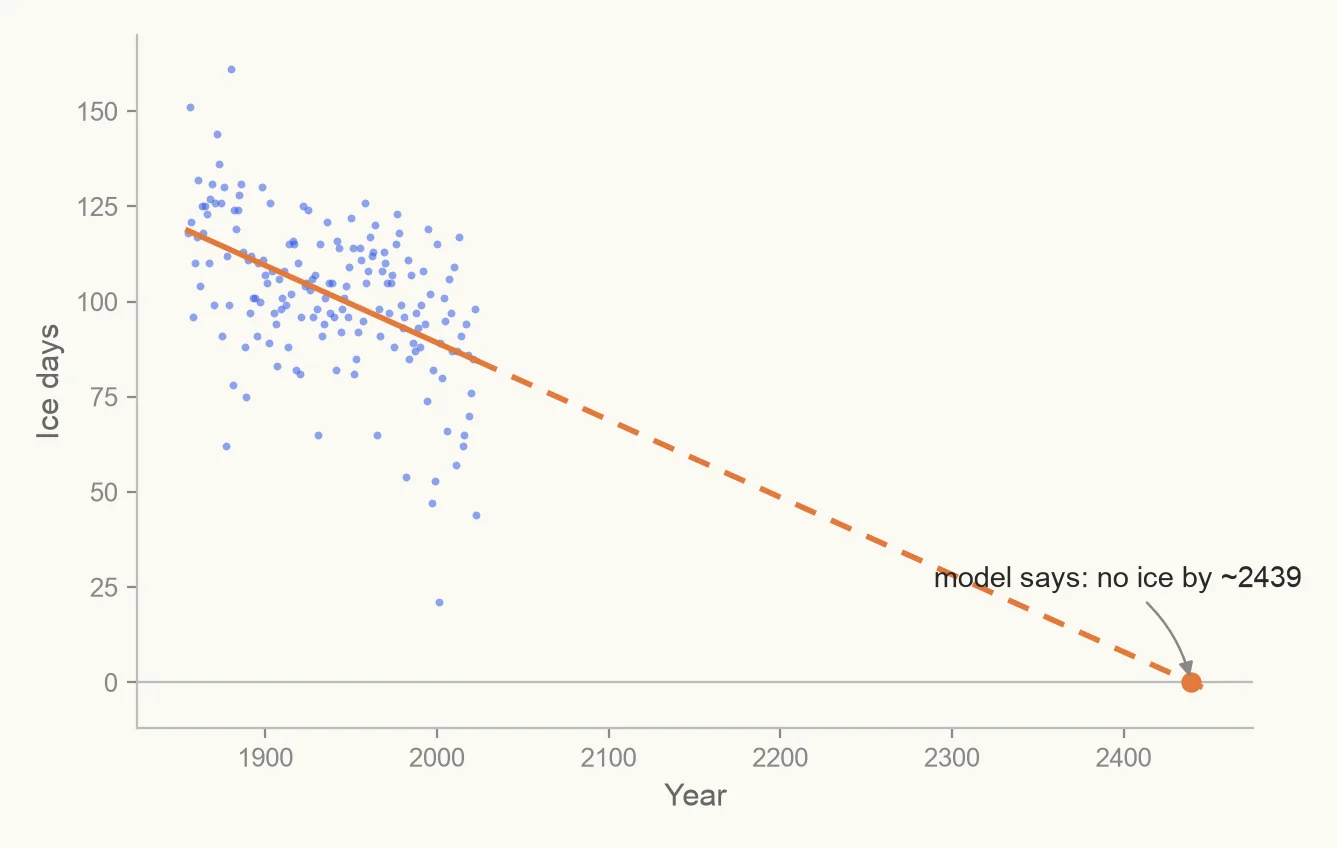
1From 1855 to 2023, the lake loses about 2 days of ice per decade: 122 days on average in the first 20 winters, 85 in the last 20.2Gradient descent, with the learning rate tuned by search, lands on the same answer as the exact solution within 200 steps.3Taken literally, the line reaches zero ice around 2439. Climate isn’t linear, so this is a lesson in the limits of extrapolation, not a forecast.
1 / 3
what I found: the trend is real and steady. Predicting far past your data is where models quietly break.
More on the way. Pass me a note if you want the details on any of these.